TL;DR
A Unified Namespace (UNS) puts signals from PLC, MES and ERP into one governed structure, so a KPI becomes a calculation on shared data and not a custom integration. This article builds this with the HiveMQ Platform and calculates Overall Equipment Effectiveness (OEE) with distributed compute in six steps.
- A topic tree is the addressing scheme. Shared meaning, governance and reuse are what make it a namespace.
- In the HiveMQ Platform you discover existing traffic, shape the namespace, turn it into a reusable data model and calculate KPIs on distributed infrastructure.
- An OEE value is only as trustworthy as the data under it, so check data health before you share the number.
Who this is for: IT/OT architects and automation engineers in Smart Manufacturing, plus plant managers and heads of digital transformation.
Two production lines report an OEE of 85 percent. Can anyone show that both lines measure the same thing? Usually not, because the inputs come from different systems: counters from the PLC, planned time from the MES and ideal cycle times from master data, each with its own topics, units and payloads.
A UNS gives all of that data one structure and one meaning. This article shows how to build one with the HiveMQ Platform and how to calculate OEE inside it. It continues our series on the data foundation for real-time operational intelligence.
In the previous article, De-mystifying MQTT vs. OPC UA: What the comparisons get wrong, we looked at MQTT and OPC UA in the Connect layer. This one covers Contextualize, the layer from the whitepaper on building a scalable data foundation that gives data its meaning.
What does a unified namespace need beyond a topic tree?
A Unified Namespace is a single, structured, event-driven source of truth for operational data across a site or an enterprise. It builds on Event-Driven Architecture (EDA): systems publish events and consume them, instead of polling each other. MQTT's publish/subscribe model is what makes this work, and a hierarchy based on ISA-95 (enterprise, site, area, line, cell) is the most common way to organize the topics.
The hierarchy is only the addressing scheme. Three more things turn it into a namespace. First, shared meaning: two systems that publish to well-named topics still have to agree on what a value, a unit or a state means. Second, governance: someone defines what a valid payload looks like before bad data reaches every consumer at once. Third, reuse: the model has to survive a new line, a new site or a new vendor without a rebuild.
UNS is an open concept, not a product. The HiveMQ Platform provides a way to implement it and its Contextualize layer covers exactly these three points.The hierarchy tells you where data lives, but not how to arrange what sits below a line. There is no single correct topic schema for that and several patterns are in use. This article uses one of them, the Orthogonal Planes pattern. It keeps the ISA-95 prefix and separates data by its purpose into planes that sit side by side in the same tree. Each plane has its own kind of content and its own writer. The physical plane holds raw machine data such as state, telemetry and metadata, written by PLCs and SCADA. The business plane holds ERP data such as production orders. The context plane holds computed values such as KPIs, written by a compute layer. The pattern could, for example, also include a batch plane and further planes, depending on your requirements.
We use this pattern because OEE draws on several sources: separate planes show where each input comes from and keep computed values apart from raw signals. It fits this use case well, but it is one possible schema and not the schema for every unified namespace.
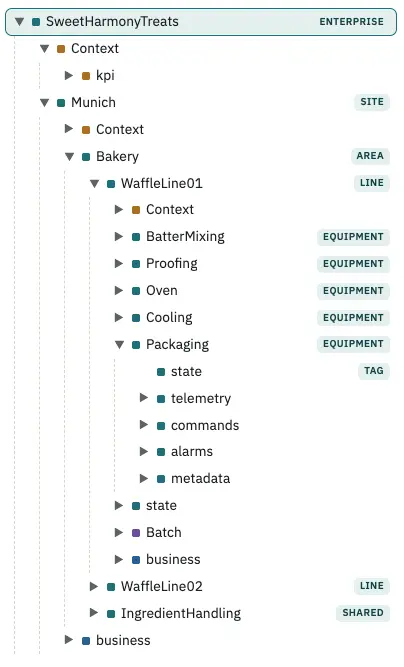
The Orthogonal Planes naming pattern: physical, business and context plane side by side under the same ISA-95 prefix
OEE calculation example: Connecting PLC, MES and ERP data in a Unified Namespace
The example is a fictional waffle producer, SweetHarmonyTreats, with one site in Berlin and one packaging cell at the end of its line. OEE is the product of three factors: availability (run time divided by planned time), performance (actual output against the output possible at the ideal cycle time) and quality (good units divided by total units).
The inputs come from four sources:
| Source | Data | Topic (below the line) |
|---|---|---|
| PLC | State, run time, total count, good count | packaging/state and packaging/telemetry/* |
| MES | Planned production time | packaging/telemetry/planned-time |
| Master data | Ideal cycle time and rated speed | packaging/metadata/capacity-spec |
| ERP | Production order | business/production-order |
We apply the Orthogonal Planes pattern from above: raw machine data (physical plane), business data (business plane) and computed values (context plane) live in separate branches under the same ISA-95 prefix. They have different owners, update rates and access needs, and a computed KPI must never be mistaken for a raw signal. The target tree looks like this:
sweetharmonytreats                      Enterprise
berlin                                Site
  bakery                              Area
    waffleline01                      Line
      packaging                       Cell
        state
        telemetry/
          planned-time
          run-time
          total-count
          good-count
        metadata/
          capacity-spec
        context/
          kpi/
            availability_pct          calculated in step 5
            performance_pct
            quality_pct
            oee_pct
      business/
        production-order              ERP data
      context/
        kpi/
          oee_pct                     calculated by hand in step 5
Payloads are plain JSON. Counters carry a value, a unit where it applies and a timestamp. Master data and orders use descriptive field names:
{
  "value": 3120,
  "unit": "s",
  "timestamp": "2026-10-09T09:34:31Z"
}{
"rated_units_per_min": 15,
"ideal_cycle_time_s": 4
}{
"order_id": "PO-4471102",
"material_sku": "WAF-CLASSIC-12PK",
"order_quantity": 5000,
"requested_delivery": "2026-10-12",
"status": "RELEASED",
"timestamp": "2026-10-09T09:34:31Z"
}Two assumptions keep the example simple. The counters are cumulative: they count from the start of the source, so the OEE describes that period. If your source resets them at shift change, the OEE starts again with the new shift. Planned time is the planned production time that has elapsed since the counters started, not the length of a whole shift. You need HiveMQ 4.55 (LTS) or later. Cloud Serverless and Starter clusters are not eligible for the data intelligence features.
Step 1: Connecting MQTT brokers on HiveMQ Platform for OEE data collection
Open Connect and add the Broker or Edge instance that receives your machine data. The Data Intelligence column shows whether it is connected to the Contextualize and Analyze features. Nothing changes for your publishers: the PLC gateway, the MES and the ERP integration keep publishing to the same broker. The namespace is a layer over live MQTT traffic, not a new transport.
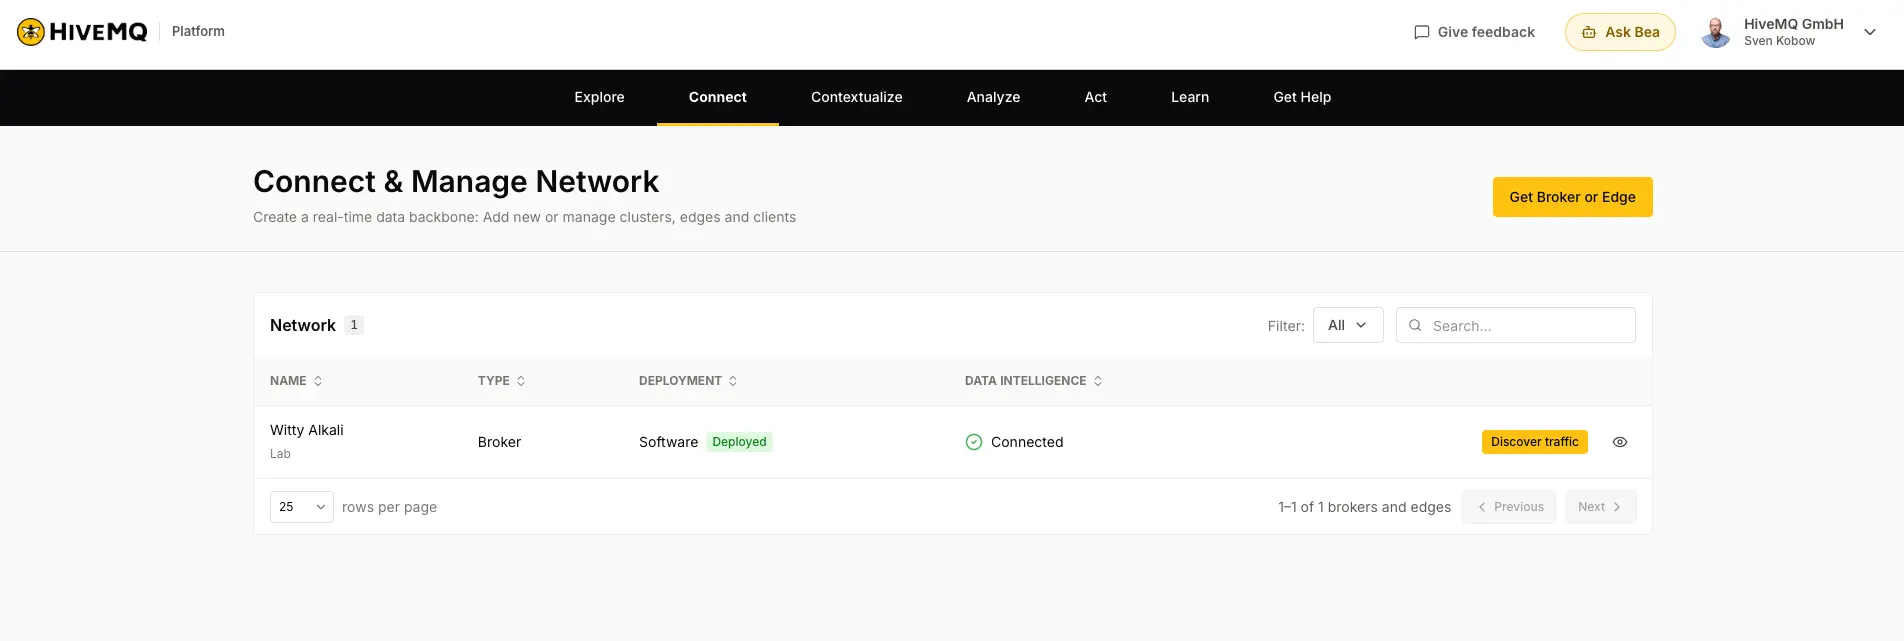
The Connect page with the broker and its Data Intelligence status
Step 2: Discovering existing MQTT data sources with HiveMQ Contextualize
Open Contextualize and the Discovery tab. It lists the ungoverned MQTT traffic of your connected brokers: topics that are flowing but are not part of any namespace yet. For each topic you see a suggested data type and serialization format, the message rate and an example payload. Approve the topics you want to keep into the namespace or ignore the rest. Approving creates the matching nodes and any missing parent nodes, and the new nodes start inactive. Topics that publish rarely, such as master data, appear only after their next message.
This bottom-up route is the fastest start. You accept what already exists and refine the structure in the next step.
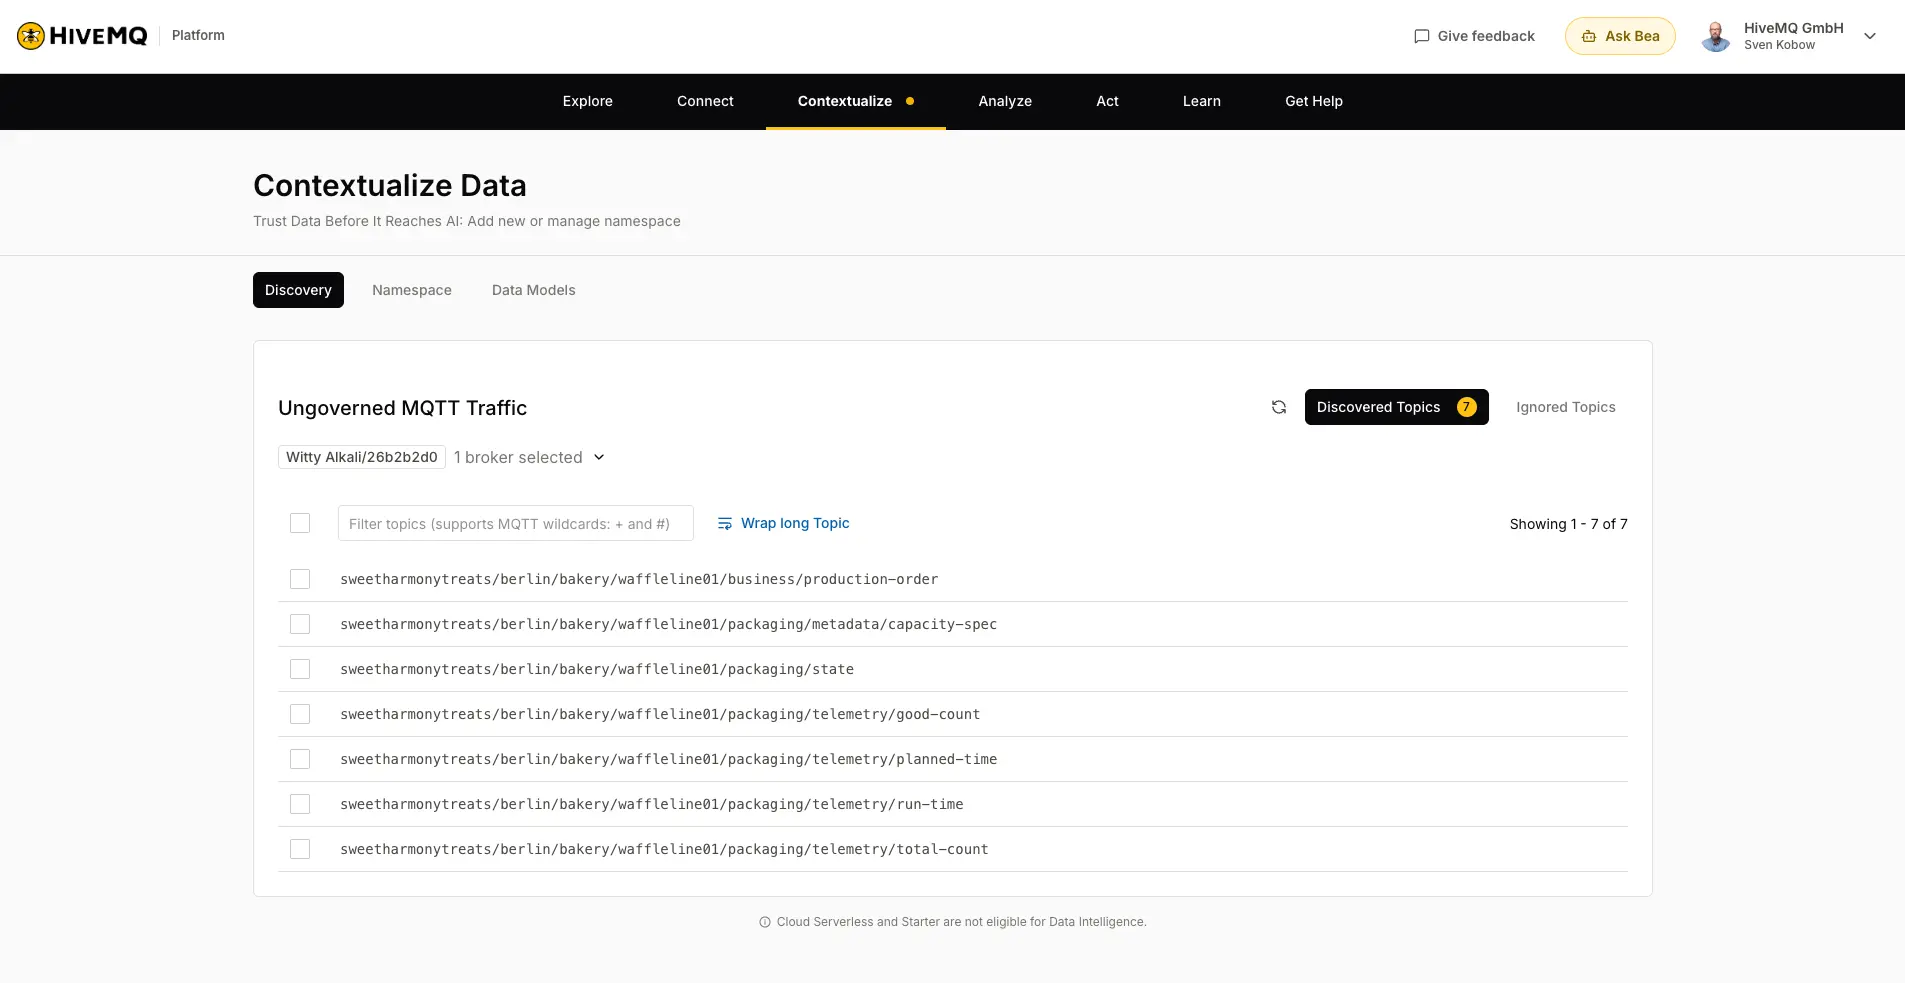
The Discovery tab with the seven discovered topics
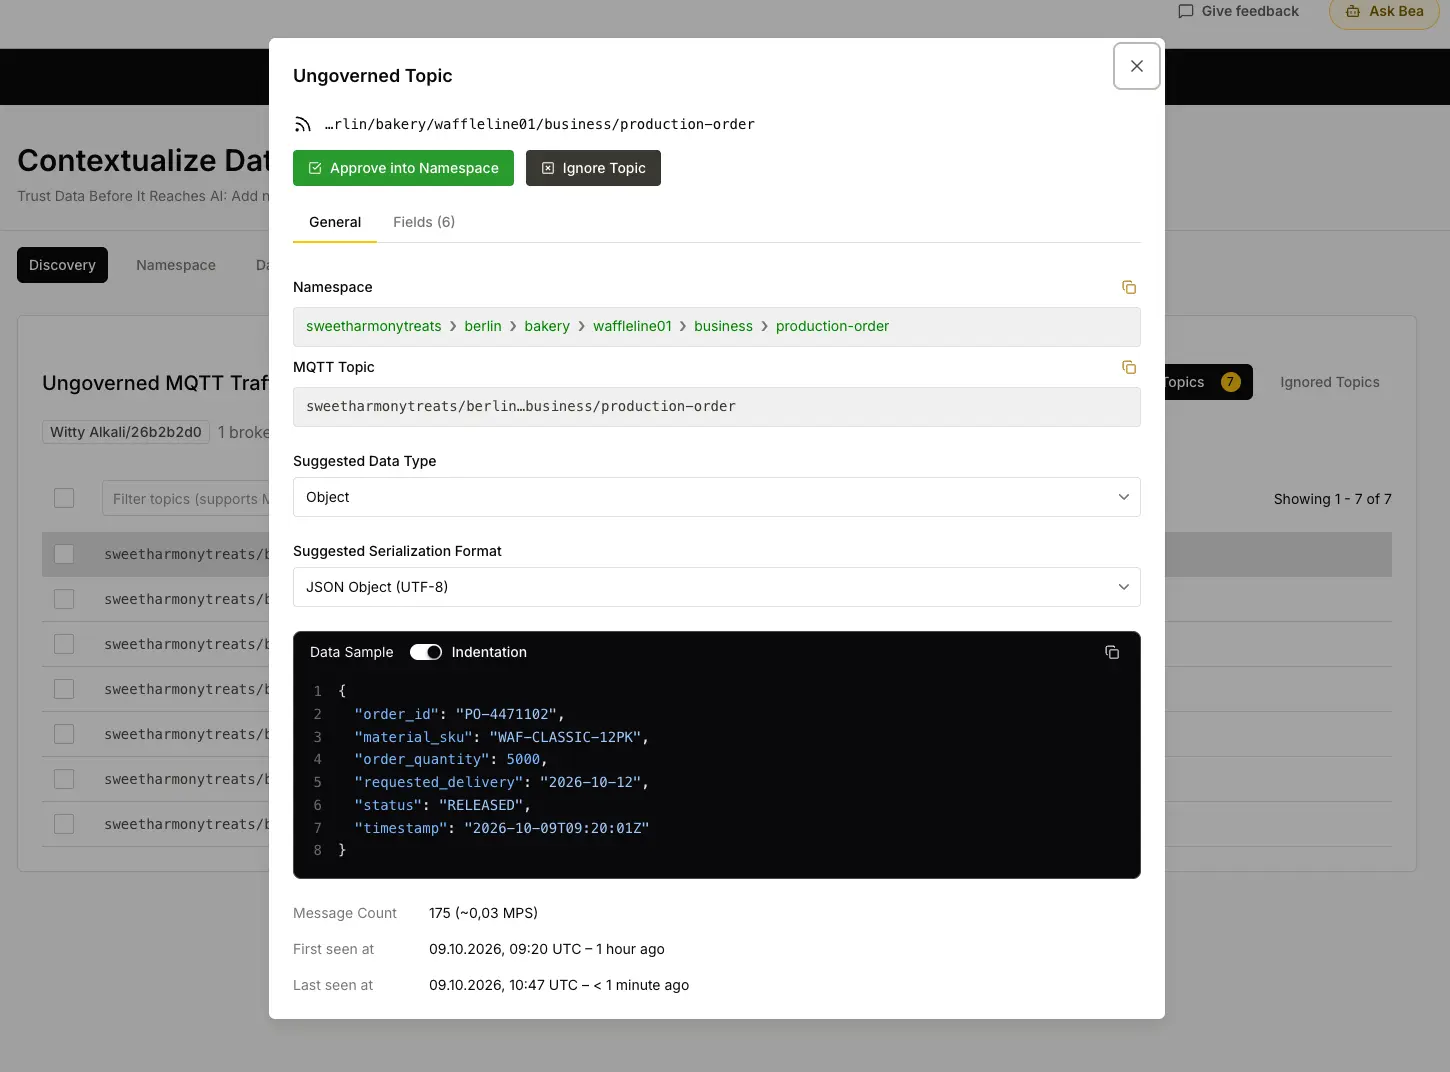
Details of a discovered topic with a preview of its payload
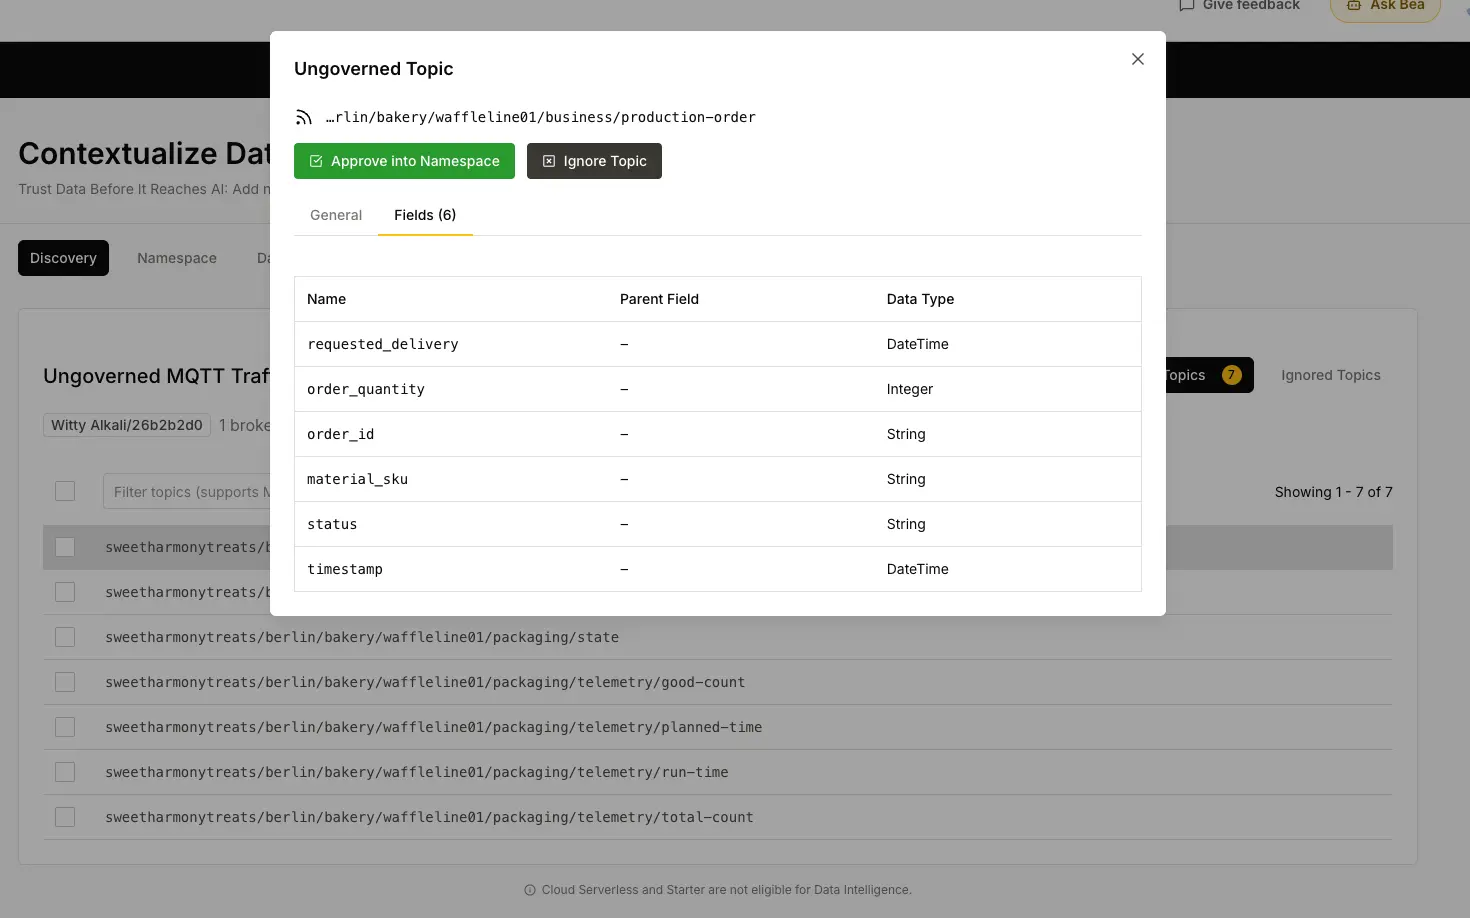
The fields Discovery inferred from the payload
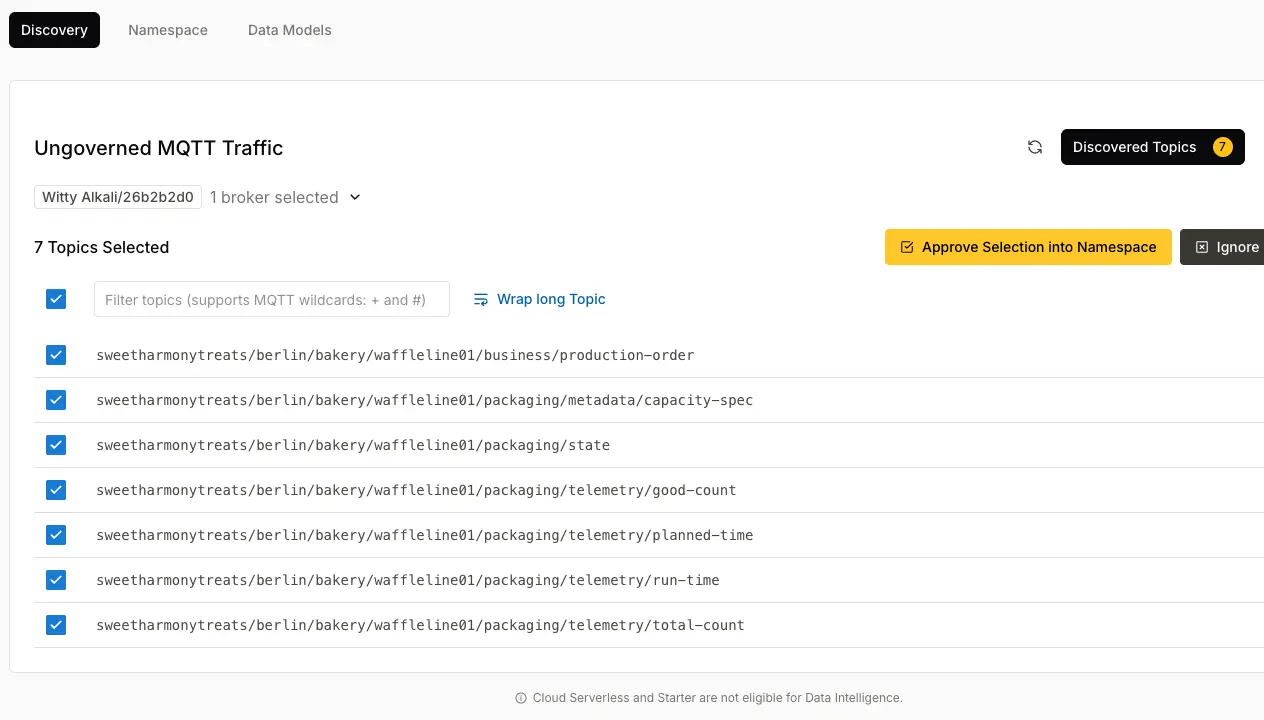
Approving the selected topics into the namespace
Step 3: Structuring and activating your Unified Namespace
Discovery has already created most of the tree, including the Field nodes it inferred from the JSON payloads, so there is nothing to build from scratch. Switch to the Namespace tab to refine what is there. The Platform offers the node types Enterprise, Site, Area, Line, Asset, Folder, Tag and Field. Two things are left to do: activate the nodes you need and set the node types, which we cover in the next section. The folders for the calculated values do not exist yet: we add them in step 5 as part of the cell model. The topic level of a node is a segment of its MQTT topic, so tree and topic stay identical.
Tags with JSON payloads get Field nodes, one per JSON key. Discovery infers them from the example payload, so you only check them and do not create them by hand. Fields give your expressions readable names. In capacity-spec they are rated_units_per_min and ideal_cycle_time_s, so a formula can refer to ideal_cycle_time_s and not to a generic value. Related data in one tag is also consumed together.
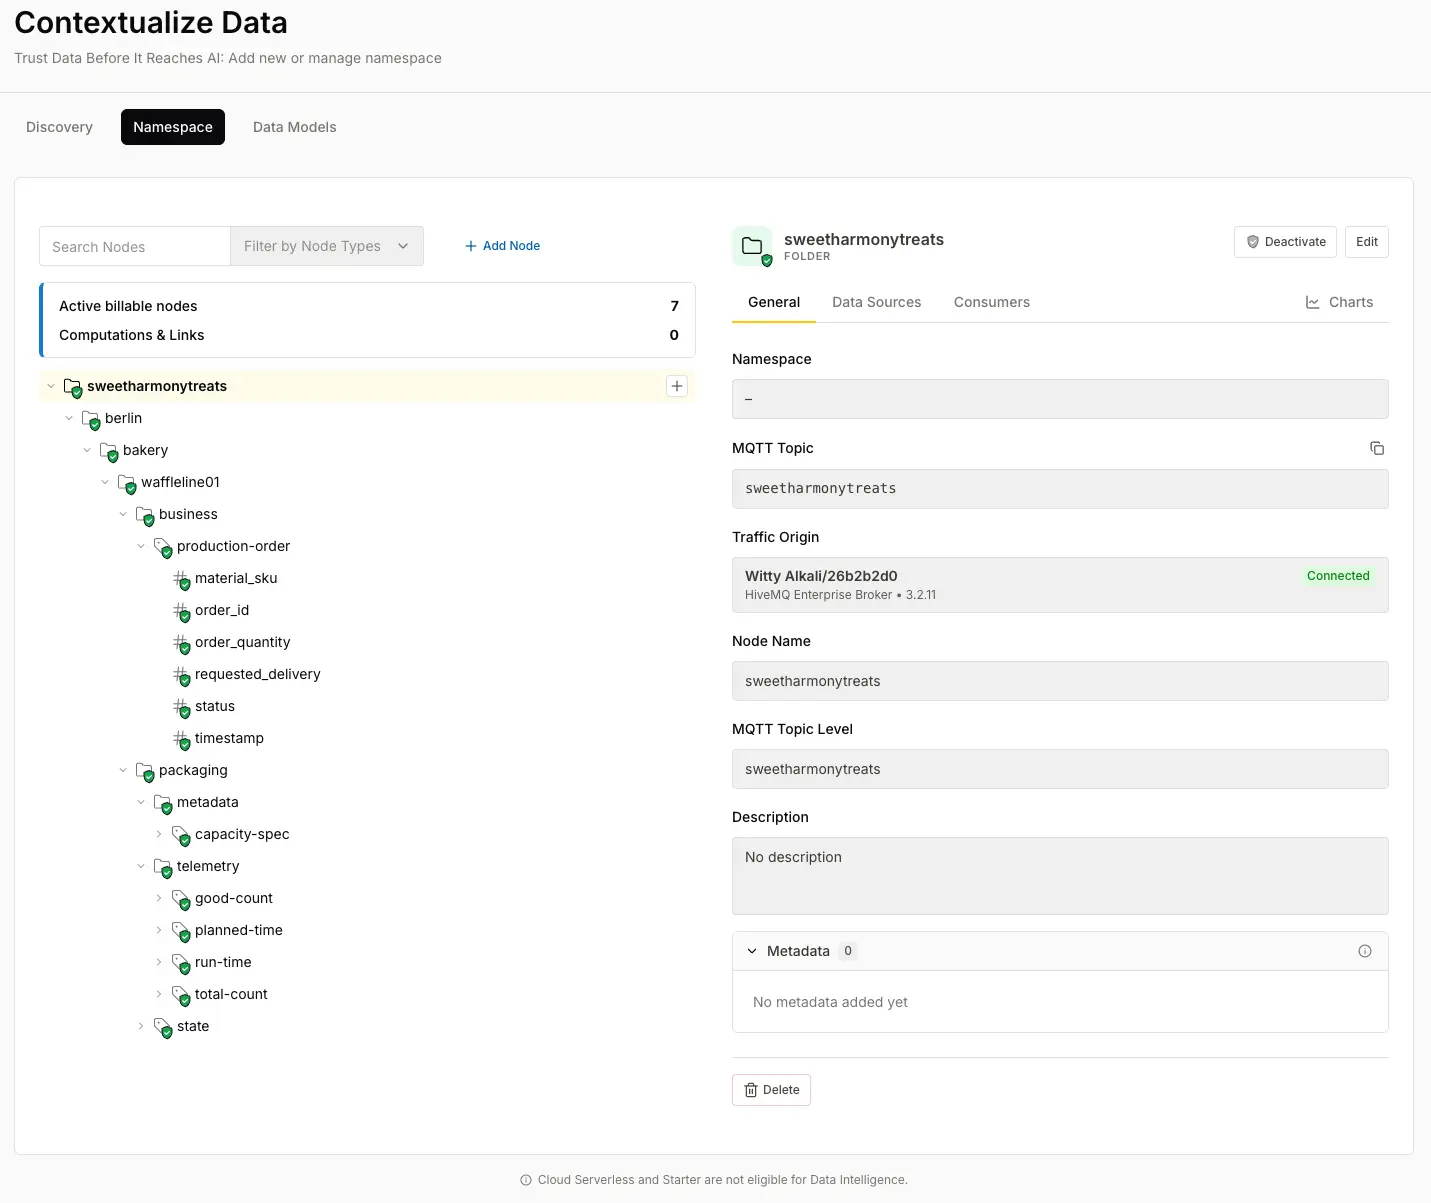
New nodes are inactive: they store no history, calculate nothing and report no deviations until you activate them. Activating a node also activates the nodes it depends on. By default a Tag keeps its latest value, so raise the history limits where a calculation needs more. Before you change or delete a node, check its Consumers tab.
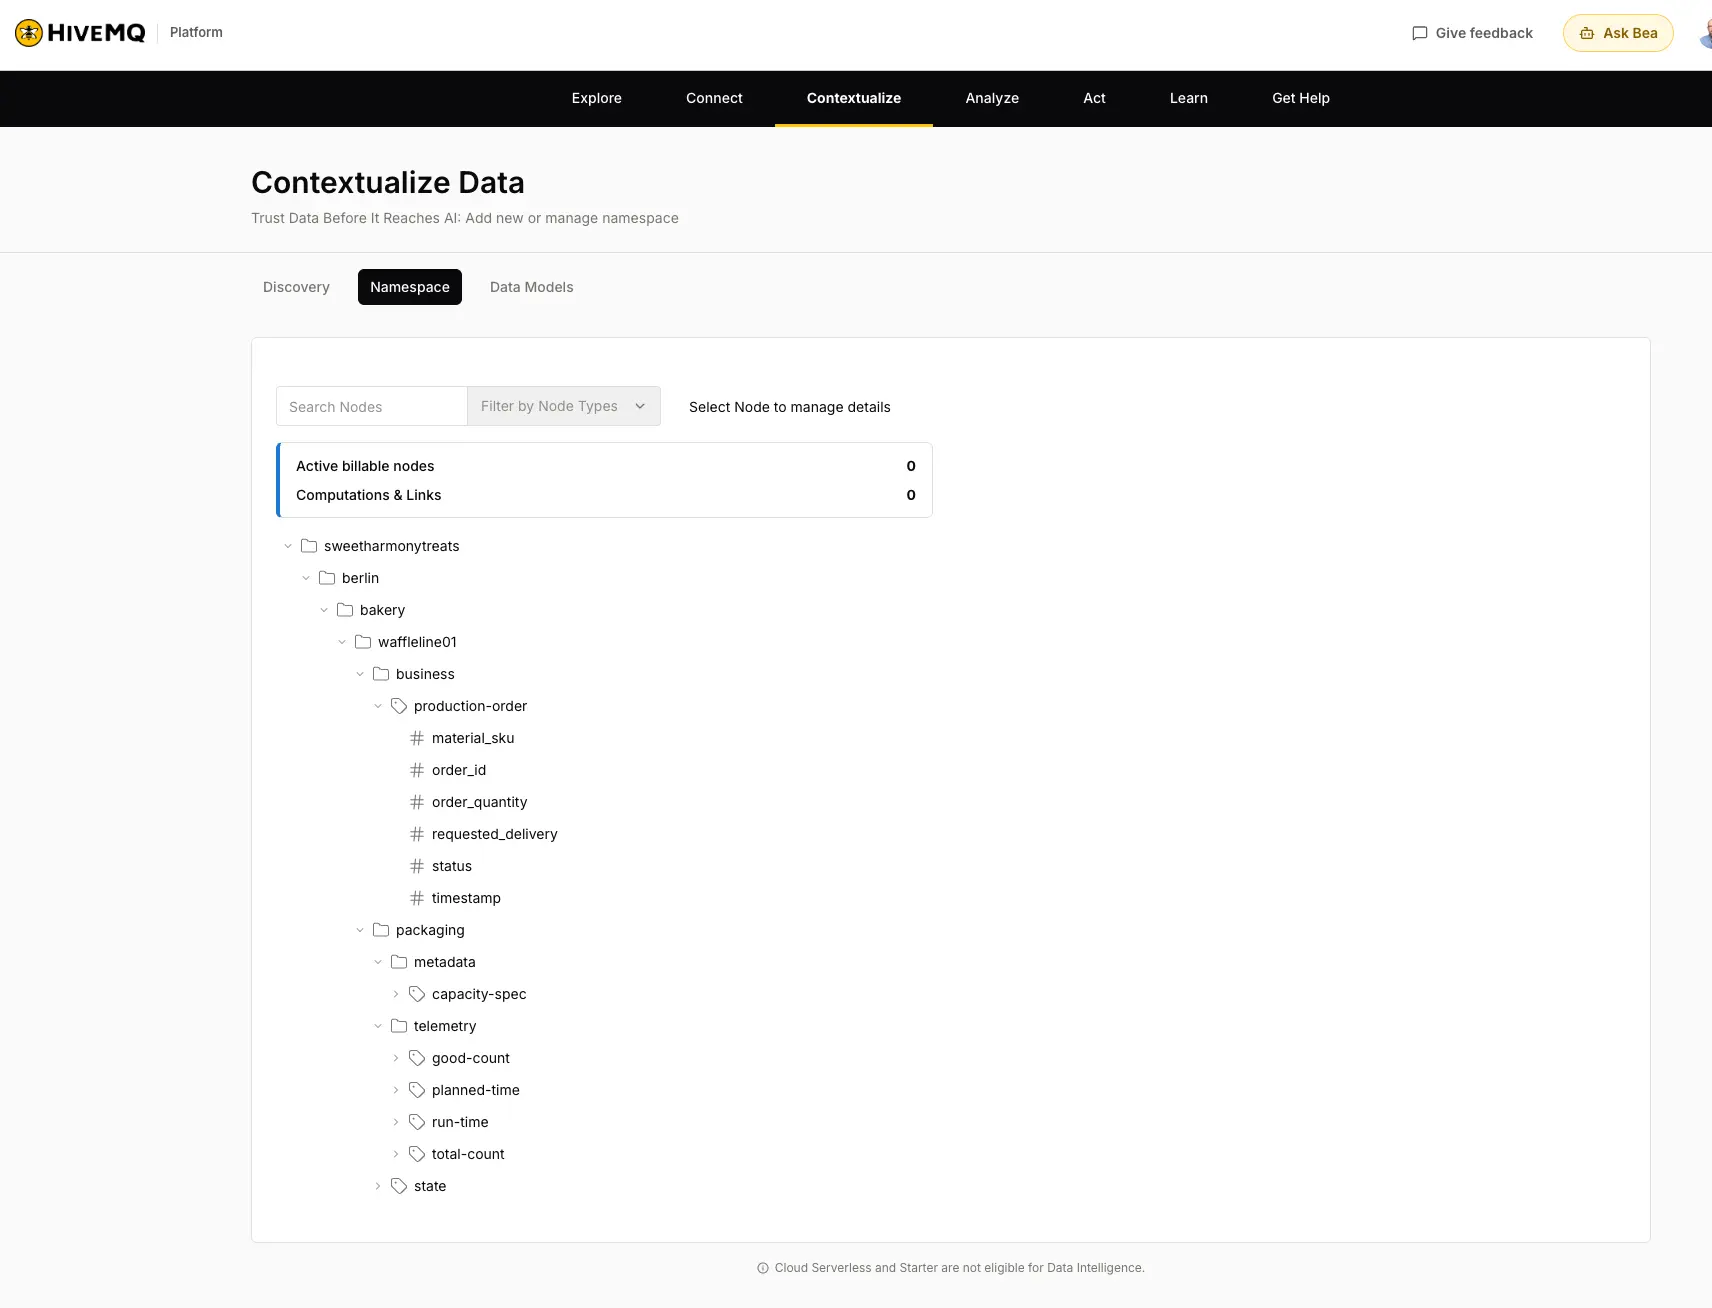
The namespace tree with the tags and fields
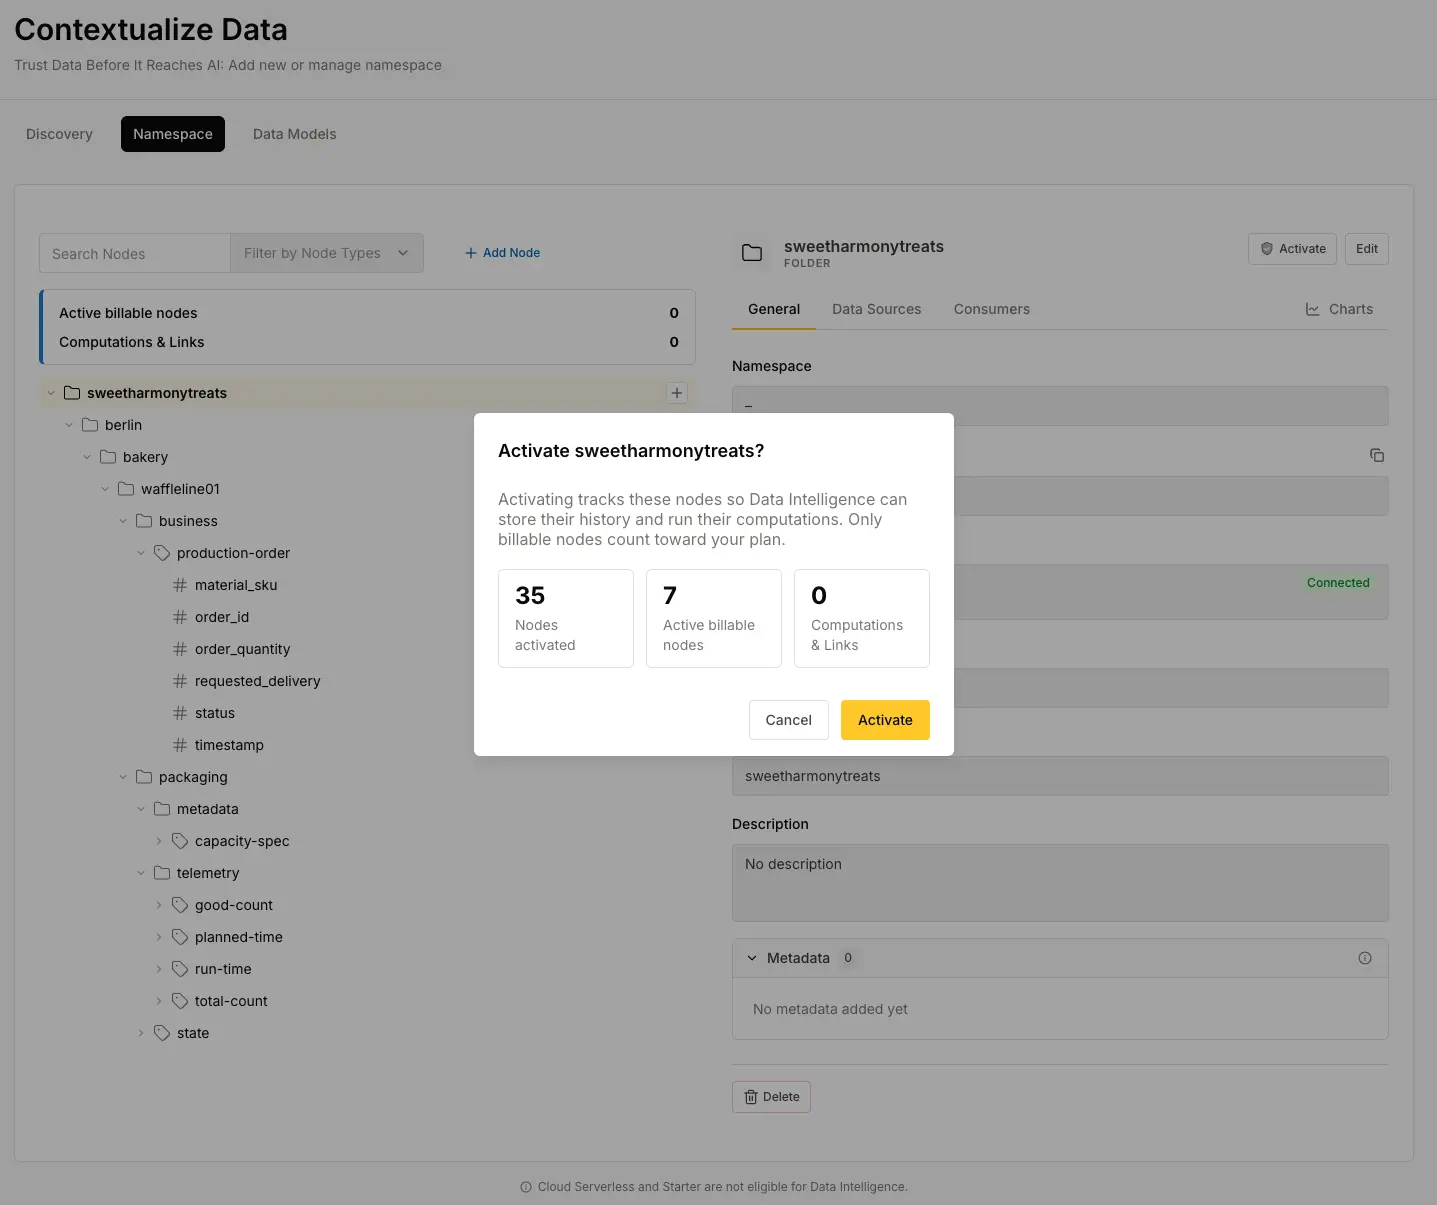
Activating a node also activates the nodes it depends on
History limits of a tag
The Consumers tab shows which nodes depend on a node
How do you adjust the ISA-95 node types after Discovery?
Discovery creates the missing parent nodes of an approved topic by itself, but it only knows the topic path, not what each level stands for. The meaning comes from the node type, so set the types now, before you build on them in the next steps.
Select a node, choose Edit in the node header and set the type. Work from the top:
sweetharmonytreats becomes an Enterprise, berlin a Site, bakery an Area and waffleline01 a Line. The cell packaging stays a Folder, as do telemetry, metadata and business. The topics you approved, such as state, run-time and capacity-spec, stay Tags.
Enterprise, Site, Area and Line are specializations of Folder.
They group nodes the same way, but the type says what a level is, and the Platform builds on it. The computations in step 5, for example, need a Site that has a relation to the broker.
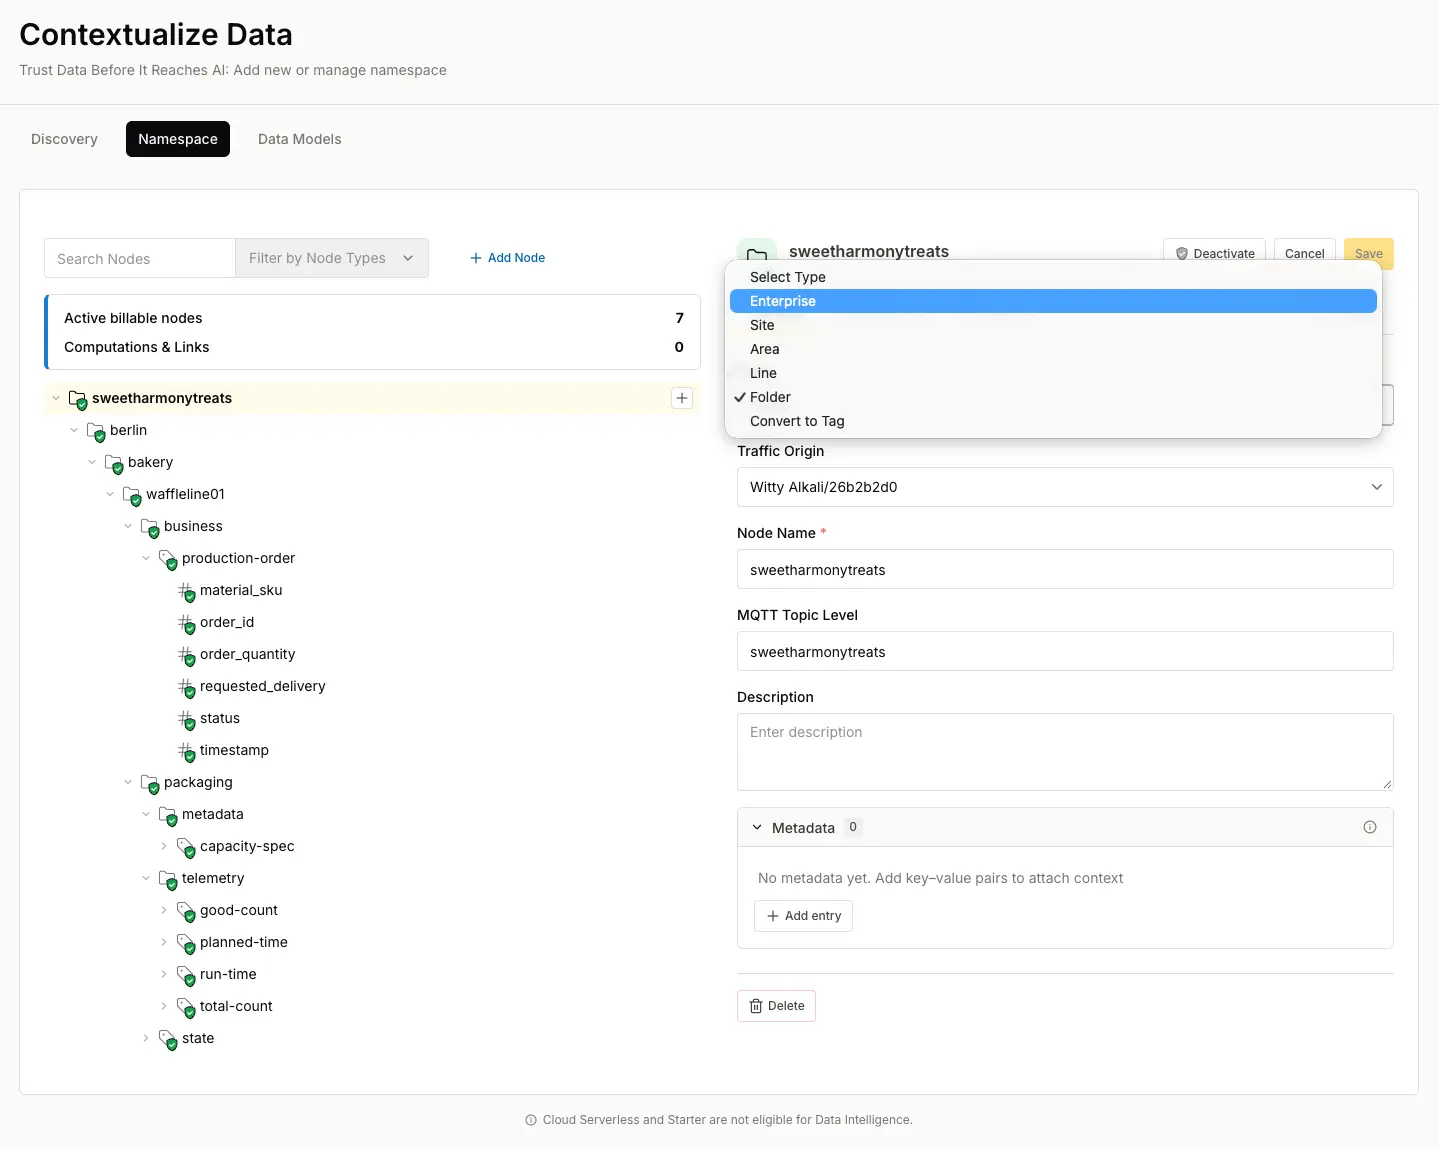
Setting the node type with Edit in the node header
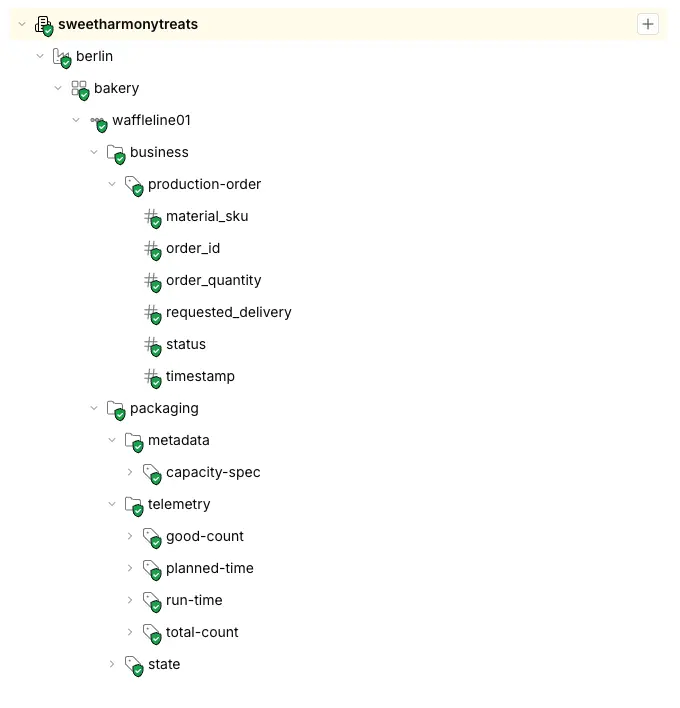
The namespace tree with the node types set
Step 4: Creating reusable data models for consistent OEE calculations
Wouldn't it be nice if you did not have to start every cell from scratch? The packaging cell is only the first of many. A real plant has dozens of cells, and each one needs the same nodes, the same field names and the same KPIs. Building them by hand does not scale, and every copy is a chance for a small difference that makes the numbers incomparable.
A data model solves this. In general, a data model is a blueprint: it describes the structure and meaning of a part of the namespace once, and you create instances of it wherever you need it. In the HiveMQ Platform you derive a model from an existing node and its subtree, replace the parts that differ with variables and publish it as a versioned model. You then instantiate it below a matching node, and existing instances can be upgraded to a new version.
Select the cell and choose Derive New Model. Replace the cell name with a variable such as {{CELL}}. Variables work in node names and MQTT topic levels and let you specify the actual values during instantiation. Publish version 1. Published versions are immutable, so every change becomes a new version, and existing instances can be upgraded to it but not downgraded.
To apply the model to the cell we already have, you currently need a detour. The topic level of an instance must be unique below its parent, so the discovered node packaging has to go first. Check its Consumers tab, delete the node, then open waffleline01 and choose Instantiate Data Model. Select production-cell in version 1 and enter packaging as the value of CELL. The Platform recreates the cell with its whole subtree.
To add a second cell, instantiate the model below a line, enter the instance name and the variable value, and the Platform creates the whole subtree. Connected brokers receive the updated information model automatically. This is what makes results comparable: a second line, in Berlin or anywhere else, gets the same structure, units and field names, so an OEE of 85 percent on one line means the same on the other. The approach could also be applied to whole lines: a model derived from a line would carry its cells and their KPIs, so a new line arrives complete.
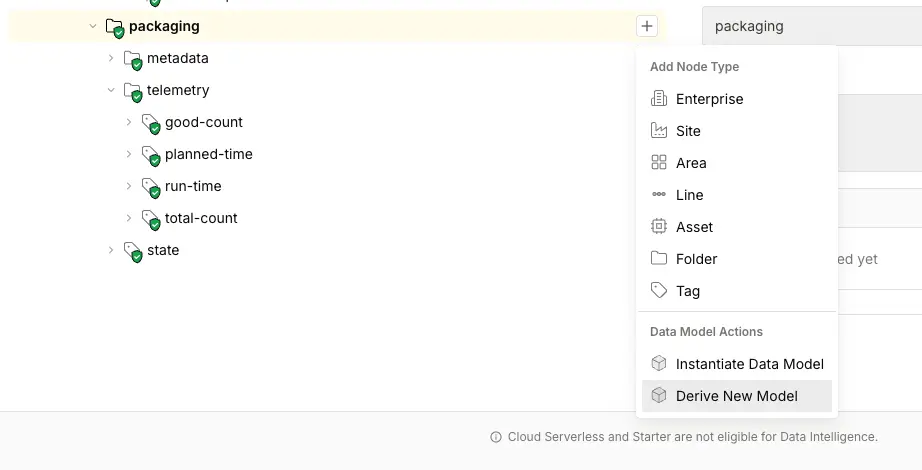
Derive New Model on the cell packaging
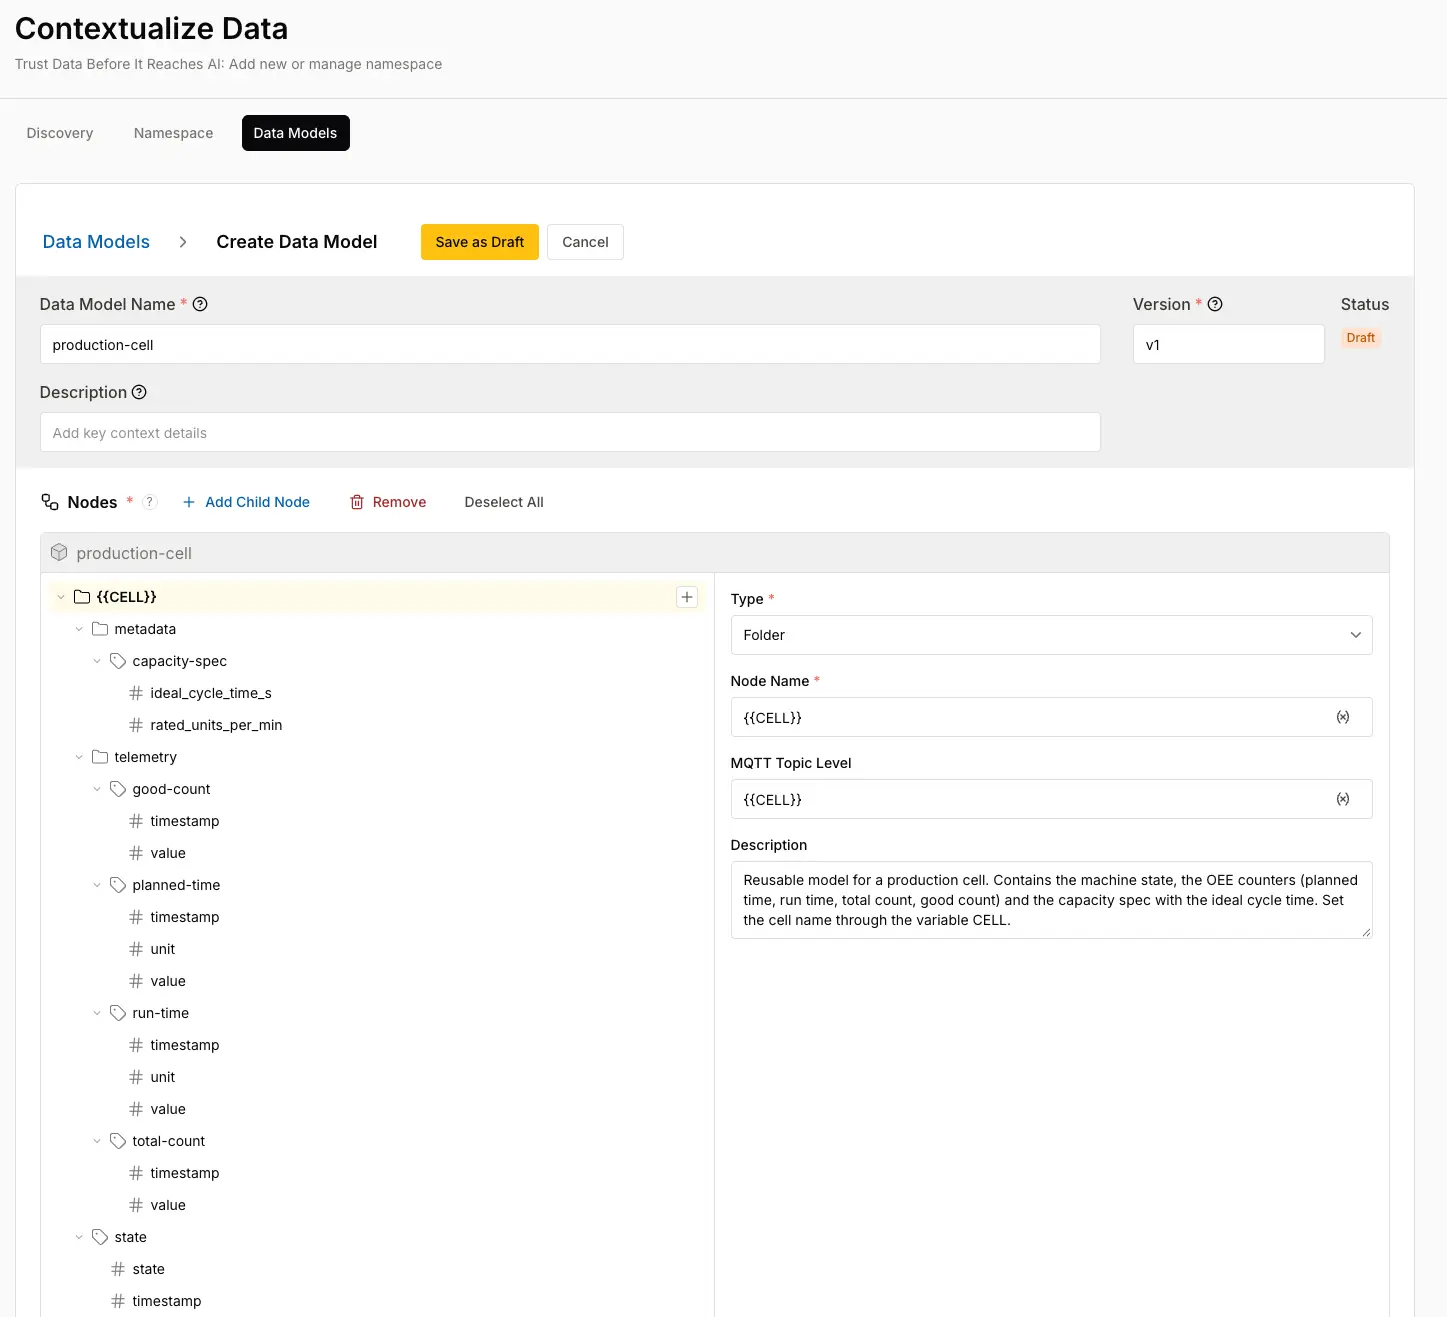
Draft of the model production-cell, with the cell name replaced by the variable CELL
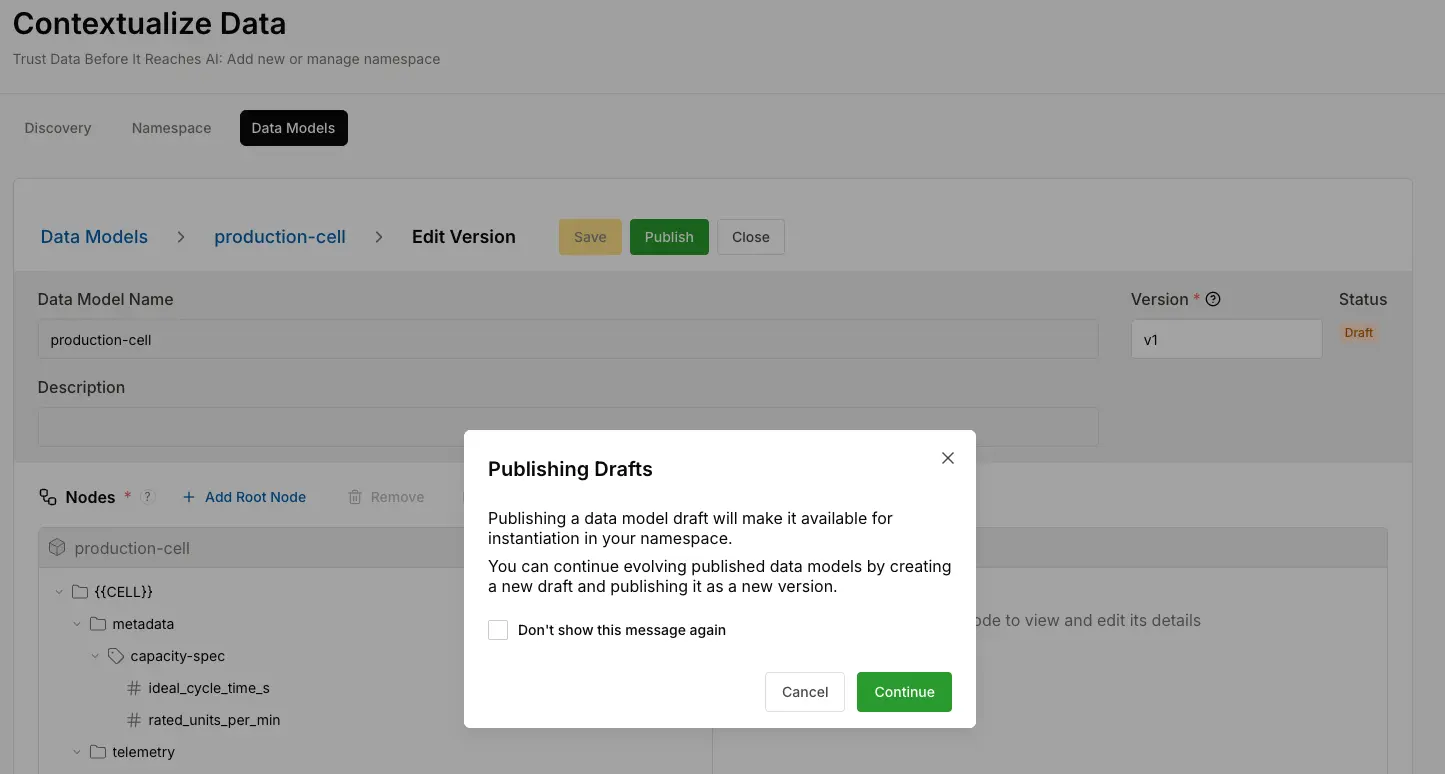
Publishing the draft makes the model available for instantiation
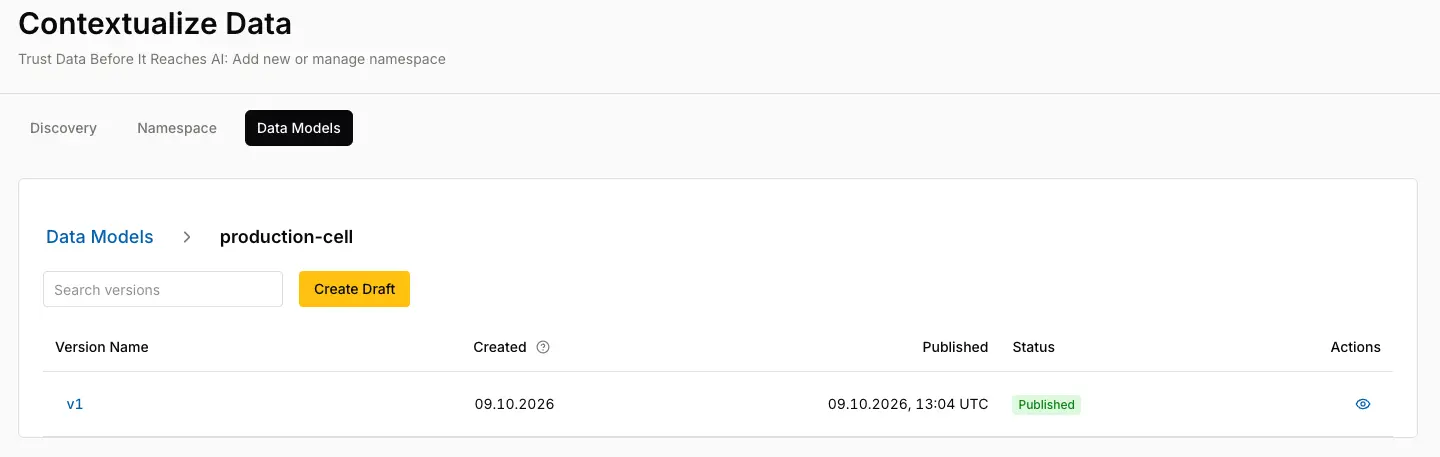
Version v1 of production-cell is published
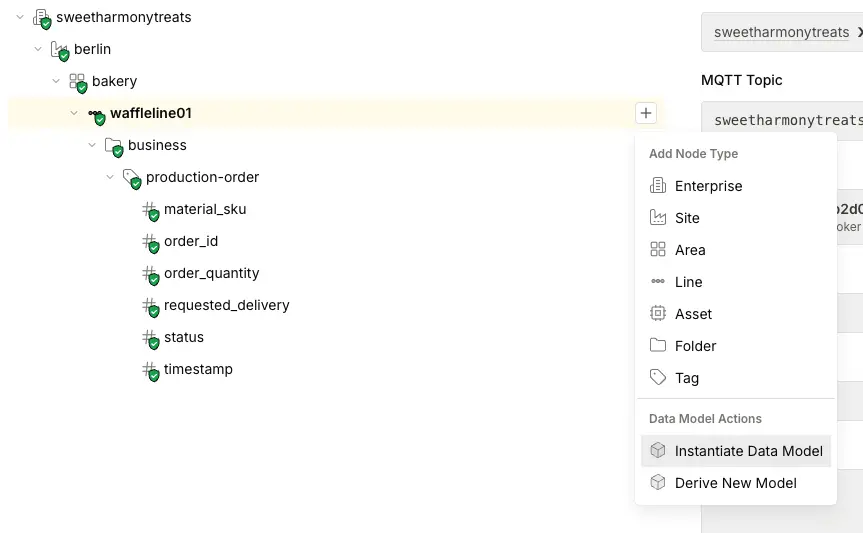
Instantiate Data Model on waffleline01, after the discovered node packaging has been deleted
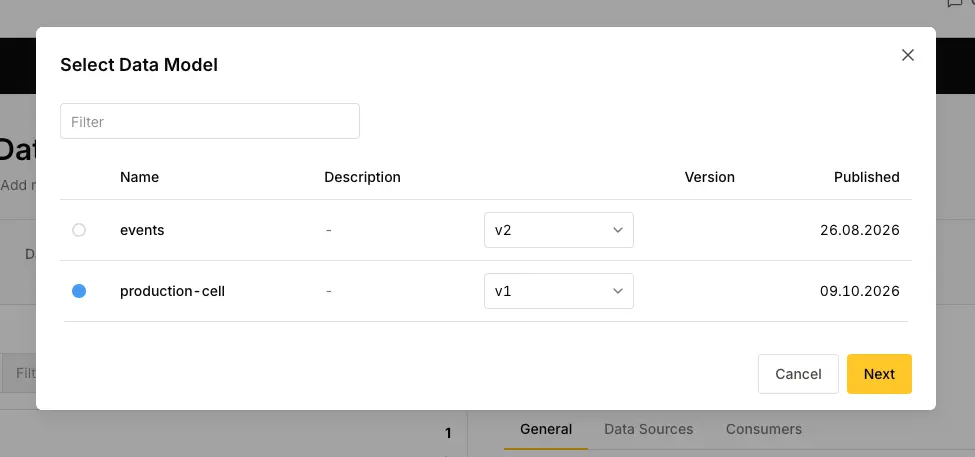
Select production-cell in version v1
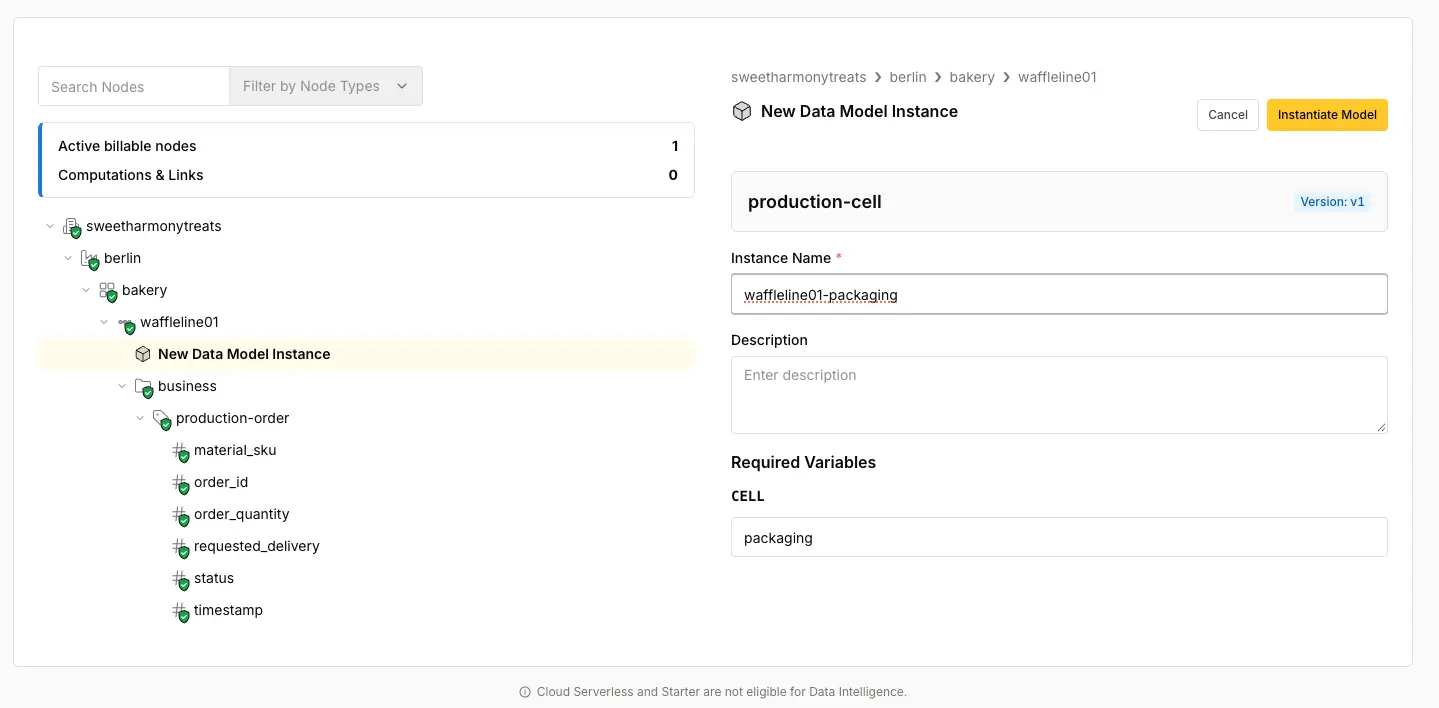
Instance name and the value of the variable CELL
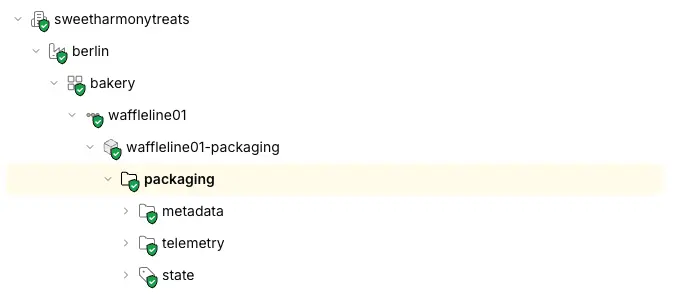
The instance below waffleline01 with the cell packaging and its subtree
Step 5: Calculating OEE using distributed intelligence in HiveMQ Platform
The HiveMQ Platform is a distributed intelligence platform: computations are not tied to one central system. The Platform distributes the compute across your connected infrastructure, for example to HiveMQ Edge instances or local site brokers. The calculation runs where the data is, with no separate stream processing system and no additional network hop. For this, a computation needs a relation between the site and a connected broker. Open the site, go to General and create a new relation with the broker as destination if necessary.
All inputs of the OEE sit in the cell, so the KPIs belong into the cell model as well. Open the production-cell data model and create a new version, v2, based on v1. Add the folders context and kpi below the cell and one tag per result below kpi. For each tag choose Expression as the data source and enter the formula. Every variable in a formula becomes an input of the tag: pick the node it reads from. Only nodes of the same model are available, which is why the counters and the KPIs live in one model.
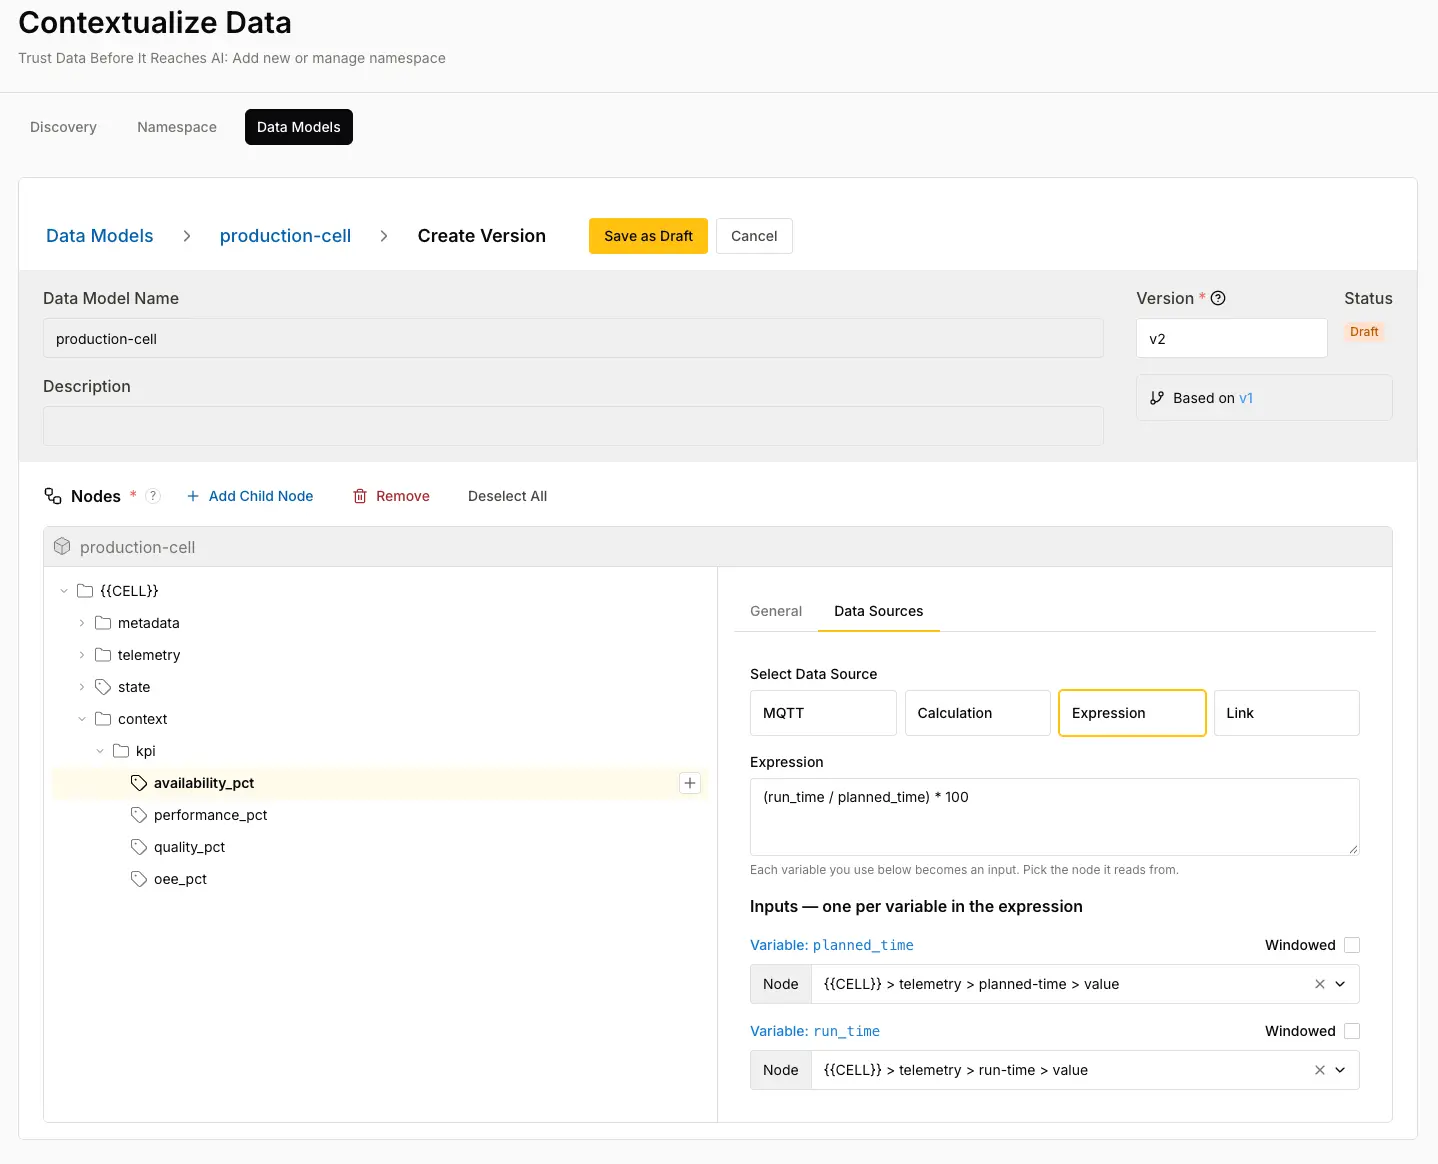
Version v2 of the production-cell model with the folders context and kpi
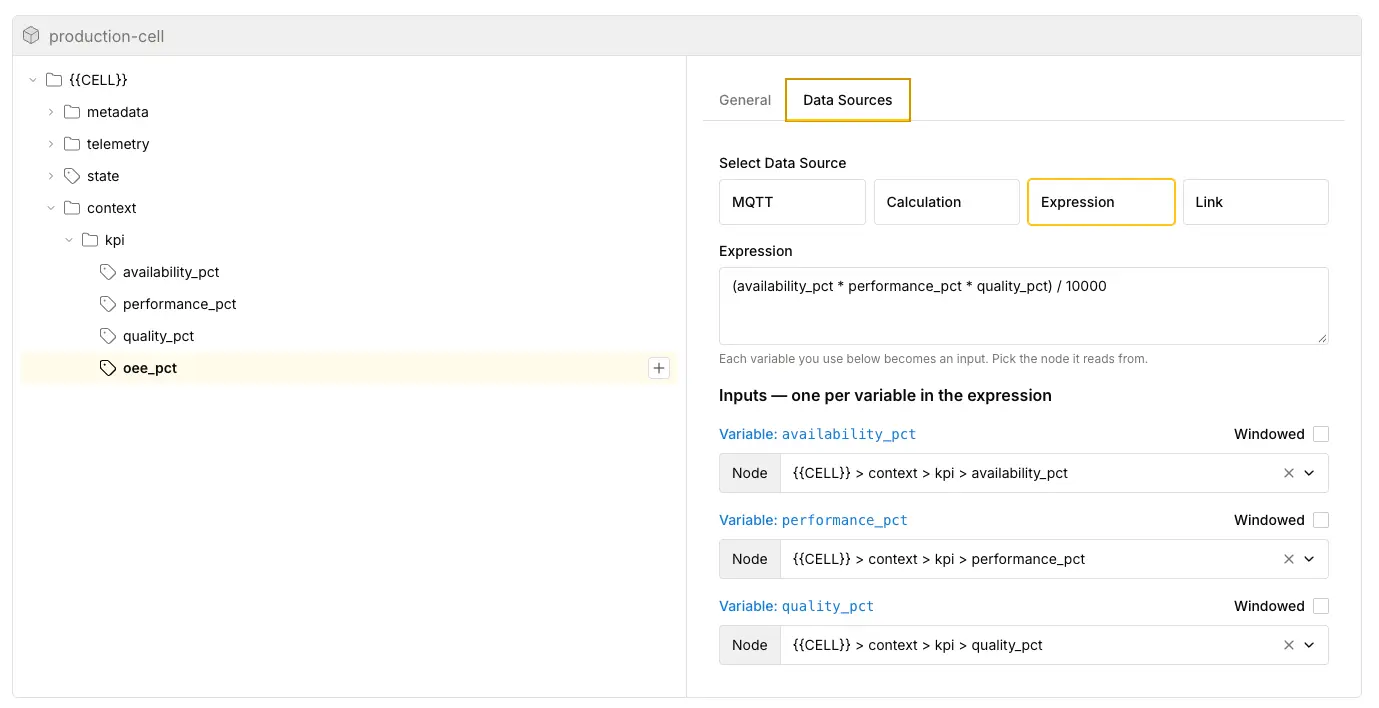
An expression tag with its formula and the inputs mapped to nodes of the model
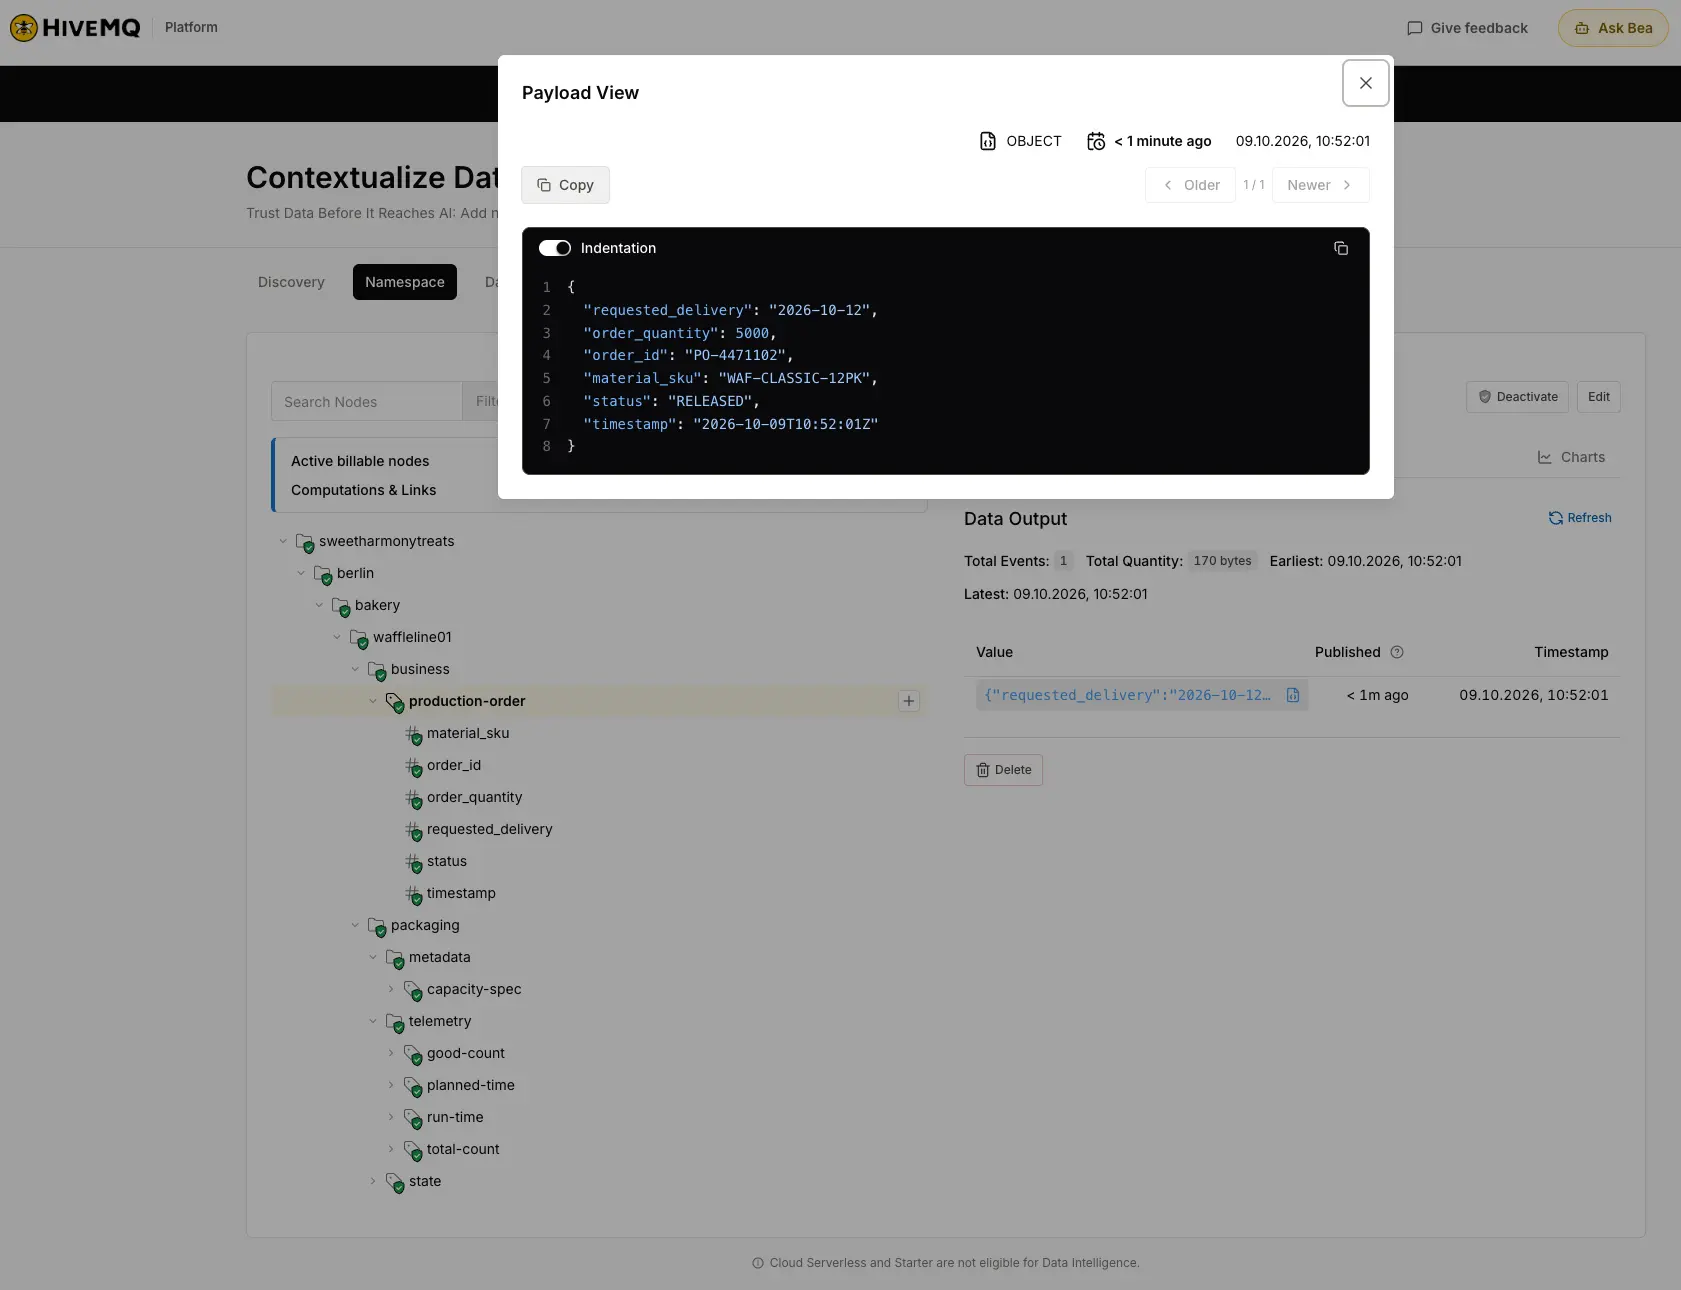
Publish v2 and upgrade the instance of packaging to it. The result appears in the Data Output tab. Because the formulas are part of the model, every cell that uses it calculates OEE the same way.
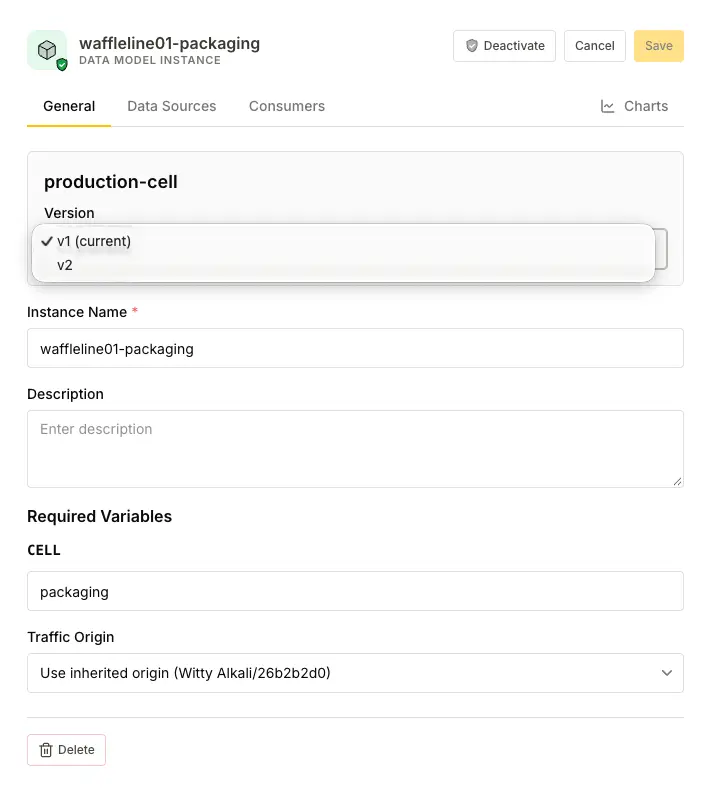
Upgrading the instance of packaging to v2
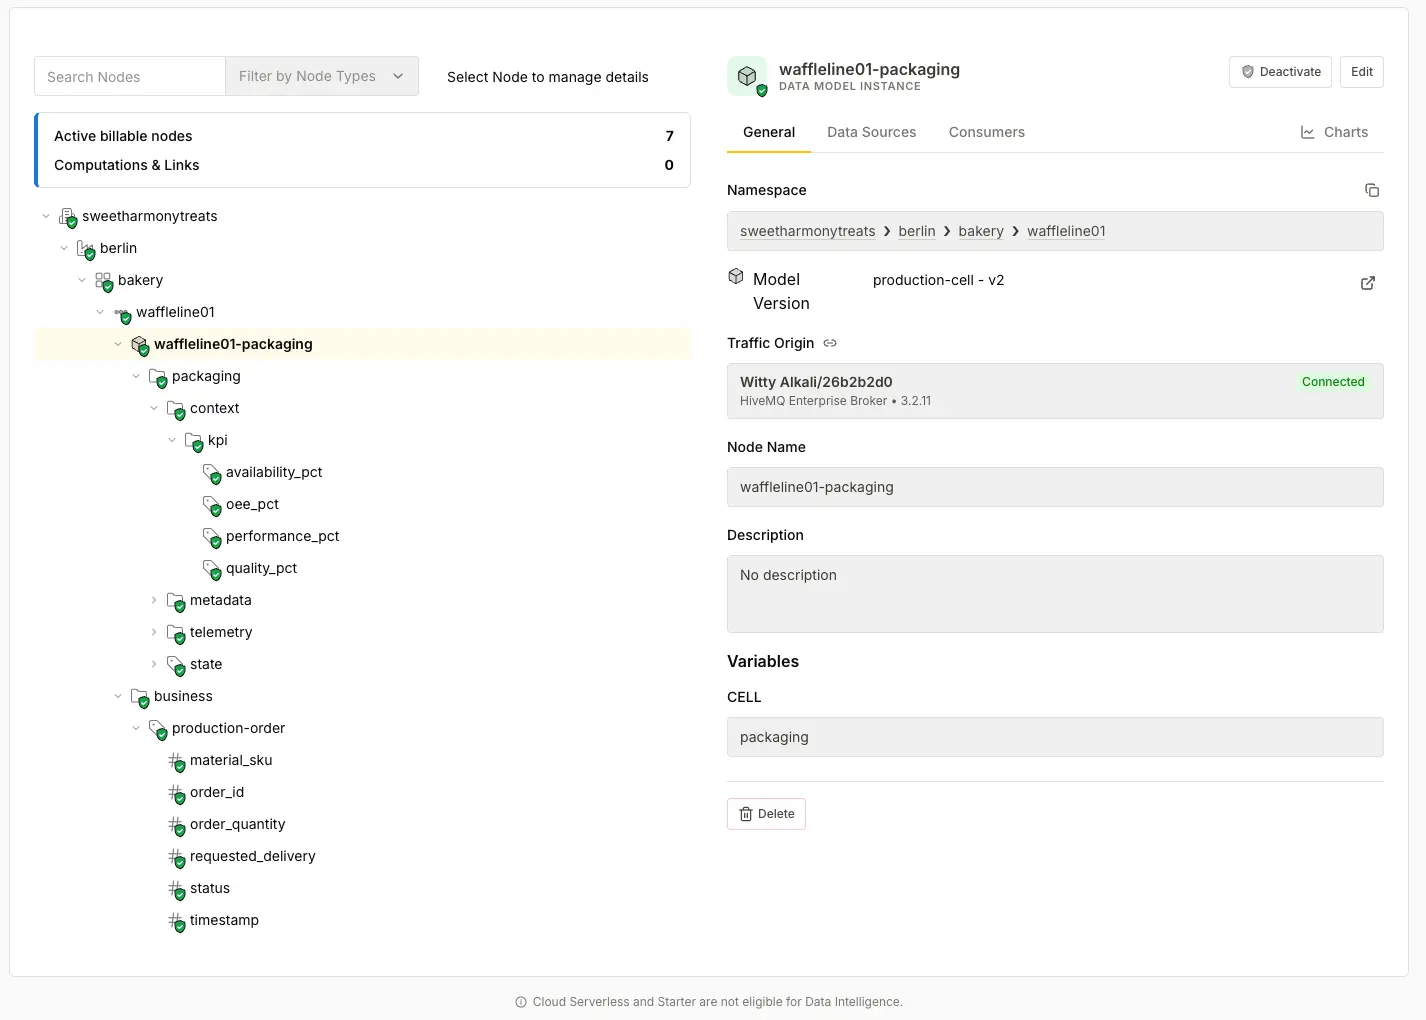
The calculated values in the Data Output tab
| Result | Formula | Inputs |
|---|---|---|
| availability_pct | (run_time / planned_time) * 100 | packaging/telemetry/run-time, planned-time |
| performance_pct | ((total_count * ideal_cycle_time_s) / run_time) * 100 | total-count, run-time, capacity-spec (field ideal_cycle_time_s) |
| quality_pct | (good_count / total_count) * 100 | packaging/telemetry/good-count, total-count |
| oee_pct | (availability_pct * performance_pct * quality_pct) / 10,000 | the three results above |
Performance deserves a closer look. The counters show how many units the cell produced during its run time. Multiplied by the ideal cycle time, that is the time the same output would have needed at ideal speed. The ratio of both is the performance factor. A cell that needs more time per unit than the ideal cycle time loses performance, and the factor drops below 100 percent accordingly.
A general example shows how the factors fit together. Assume a planned time of 600 seconds, a run time of 450 seconds, an ideal cycle time of 4 seconds, 90 units in total and 85 good units. Availability is 450 / 600, so 75 percent. Performance is (90 × 4) / 450, so 80 percent: the cell needed 5 seconds per unit instead of 4. Quality is 85 / 90, so 94.4 percent. Multiplied, this gives an OEE of 56.7 percent. The three factors share terms that cancel out, so the product shortens to good units × ideal cycle time / planned time: 85 × 4 / 600 gives the same 56.7 percent. The values in your own namespace differ with the counters of the cell, but the calculation stays the same.
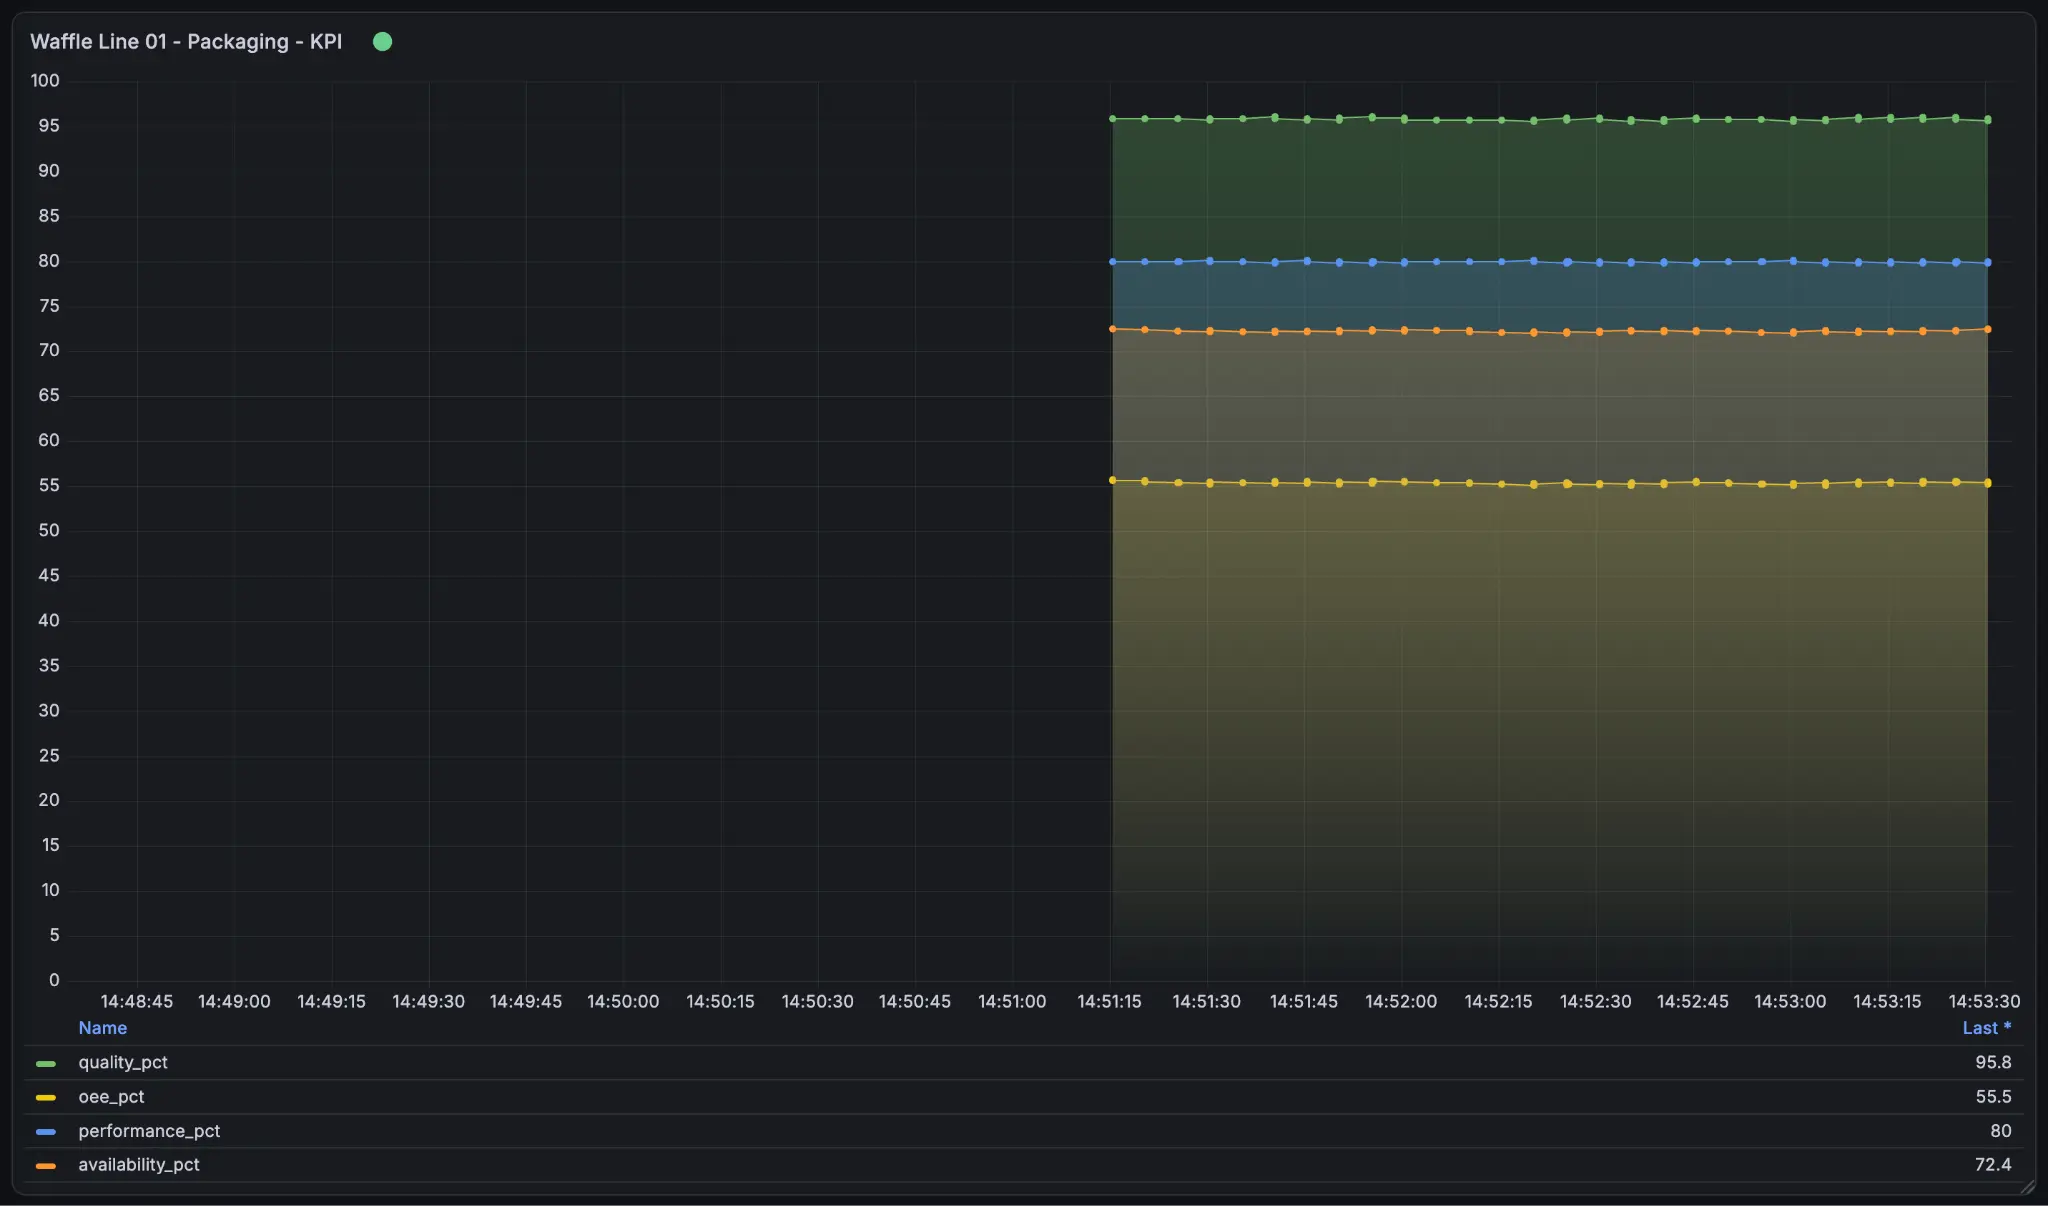
The OEE and its factors on a dashboard
If you prefer state-based reliability KPIs, the same namespace supports them. The state topic and the BetweenState function calculate MTBF, MTTR and availability, as described in our article on real-time reliability KPIs.
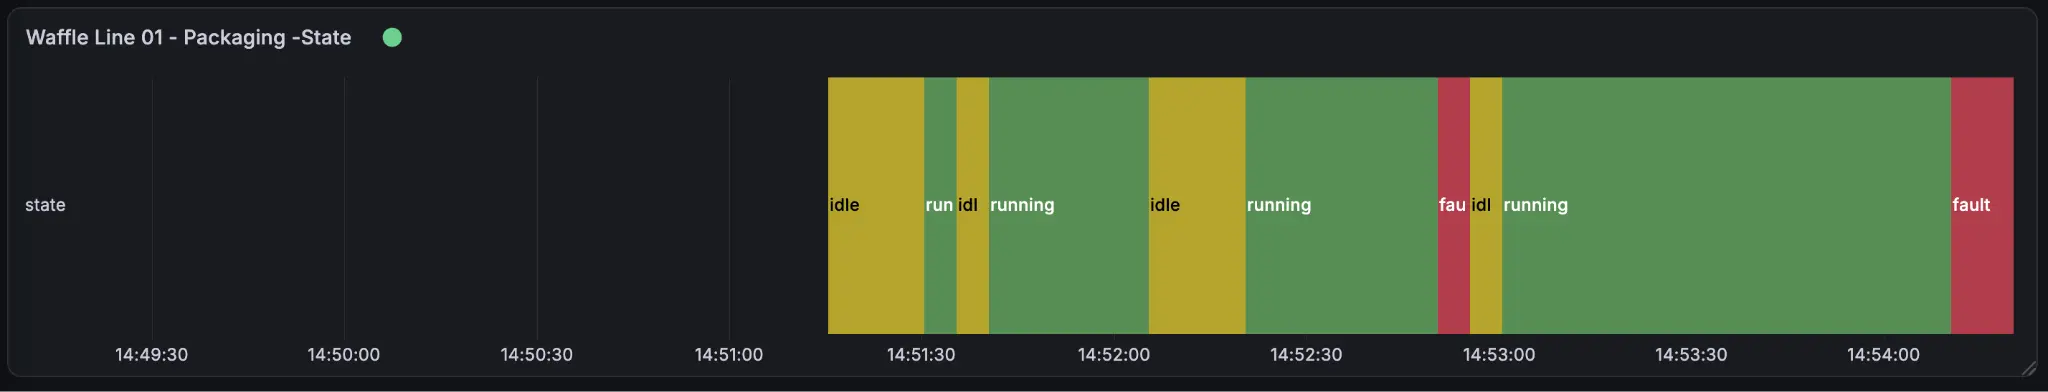
MTBF, MTTR and availability calculated from the state topic
Computations can also run over the stored history with the Windowed option, for example for a rolling window instead of a shift.
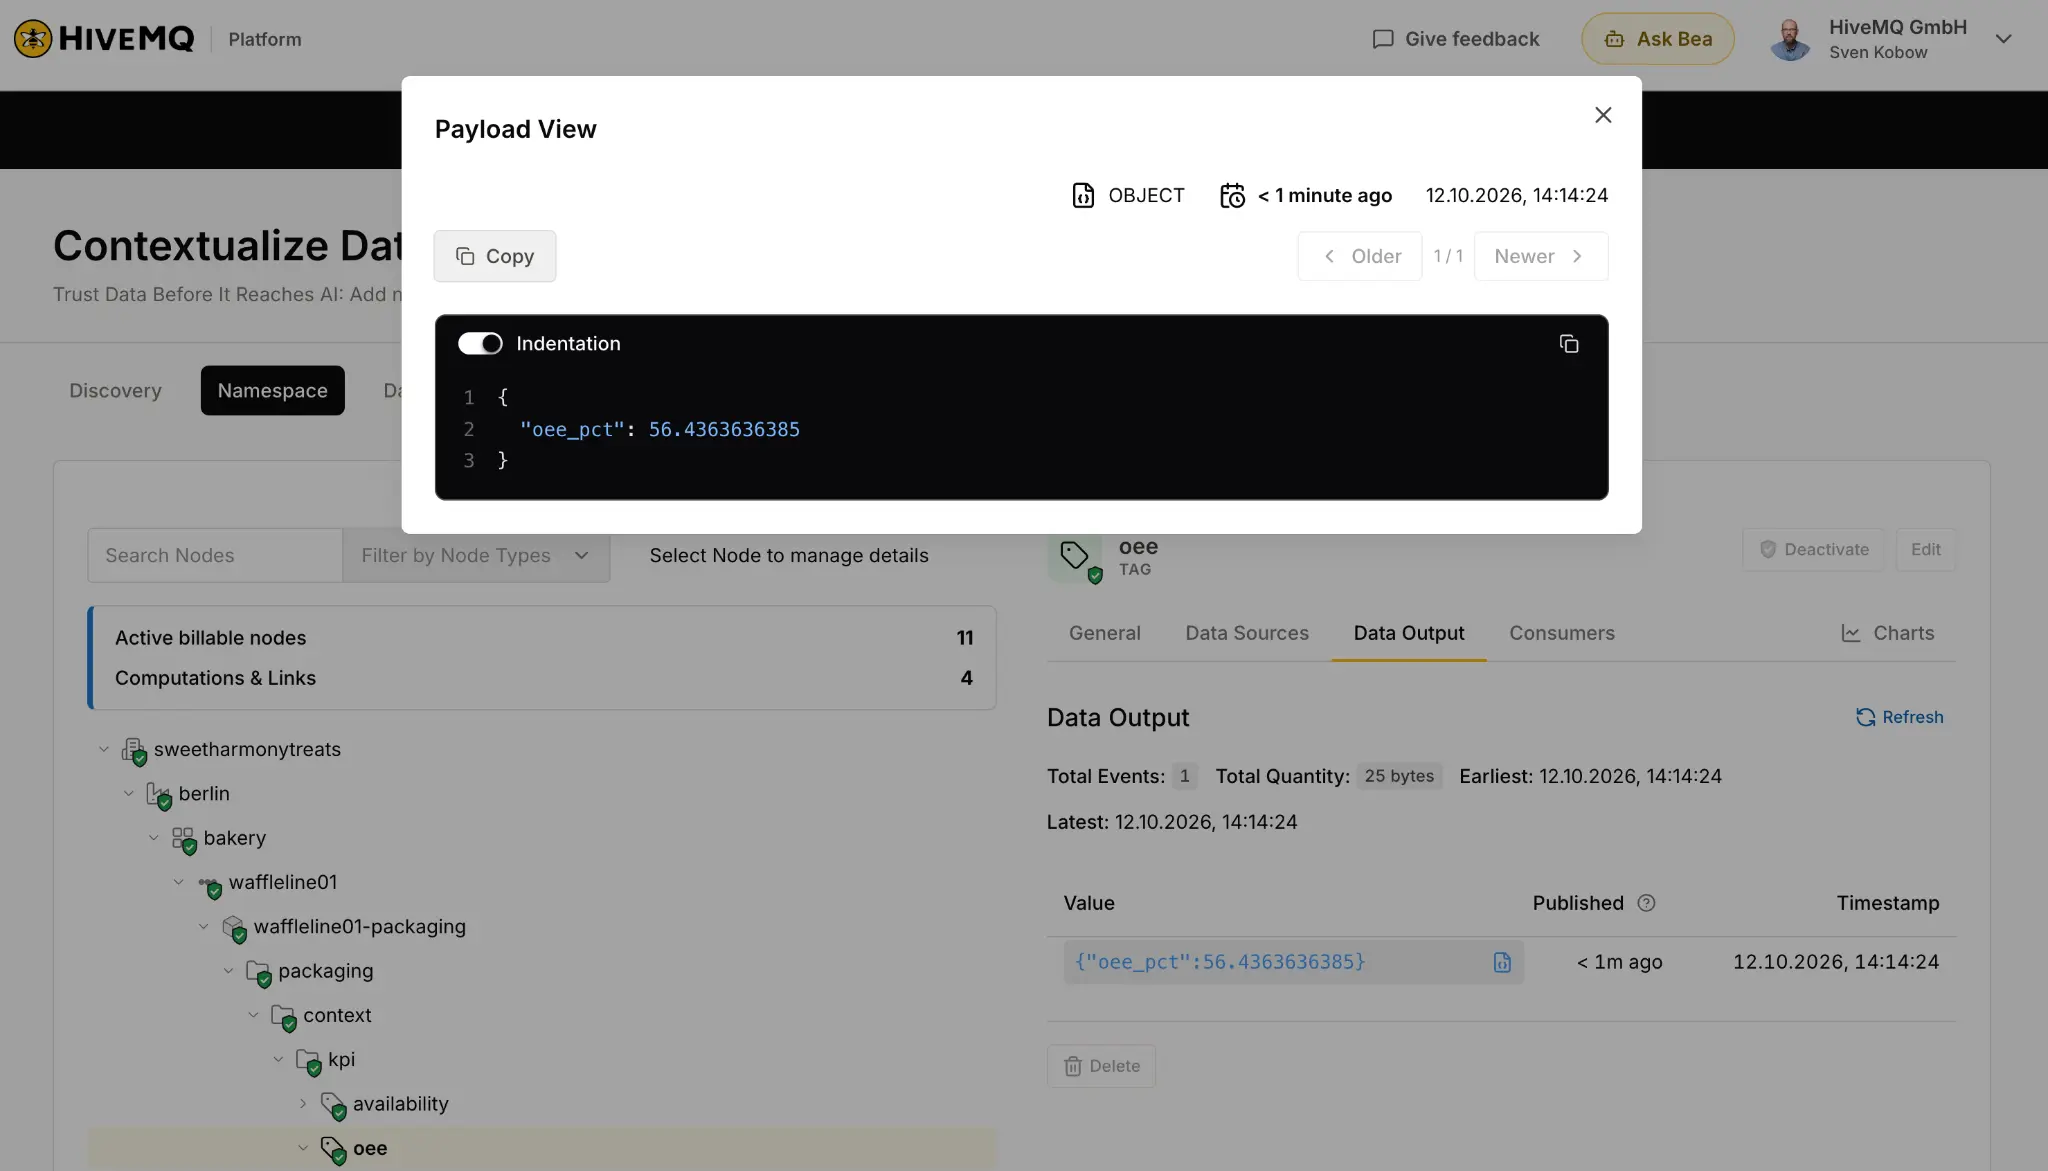
A computation over the stored history with the Windowed option
How do you calculate the OEE of the line?
The cell model gives every cell its own OEE. The line needs a value of its own, and it is not the average of its cells. In this example the line has one cell, and its output at the end of the line is what counts. Create the folders context and kpi directly below waffleline01, outside the model, and add the tag oee_pct. Choose Expression, enter (good_count * ideal_cycle_time_s) / planned_time * 100 and map the variables with Add Source to the nodes of the packaging cell. With a single cell the result equals the OEE of the cell, but it now sits at the level of the line, where a dashboard or an agent looks for it.
With several cells the formula changes, not the approach. For parallel cells of the same kind, add up the good units times the ideal cycle time of every cell and divide by the sum of their planned times. For cells in series, use the output at the end of the line against the ideal cycle time of the slowest cell. A simple average of the cell values would be misleading, because a cell with a short planned time would weigh as much as the others. An expression outside a model can read the nodes of any cell, so it can combine them.
How do you add the running order to the KPIs?
Computations are not the only way to derive a value. A Tag can also use Link as its data source, which mirrors another node. That carries context from one plane into another without a new interface. Create a tag current-order-id in the context folder of the line, choose Link as the data source and point it at the order_id field of business/production-order. The order stays in the business plane, and the context plane now shows which order is running while the KPIs are calculated.
Keep the limit in mind: the counters run over time, not per order. The link tells you which order is running. It does not turn the KPIs into order KPIs.
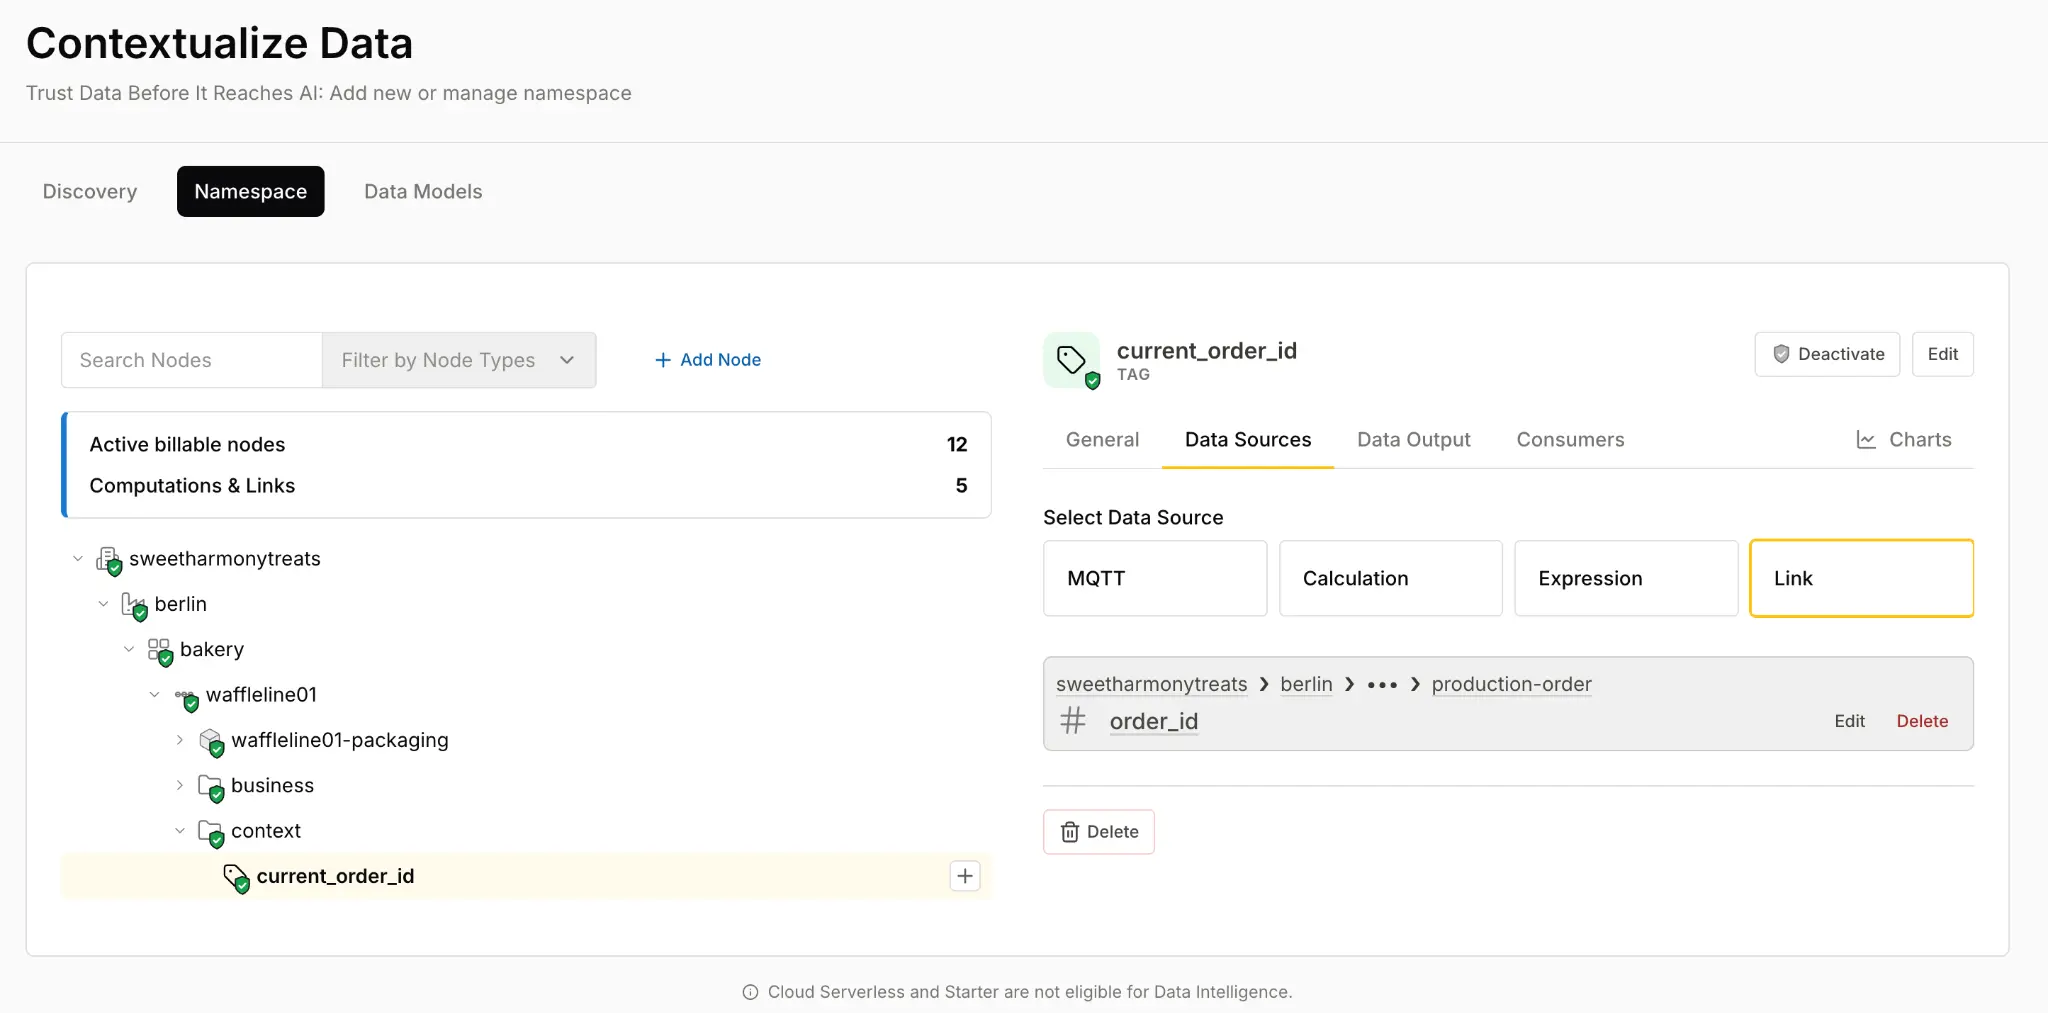
The tag current-order-id with Link as its data source
Step 6: Validating OEE data quality with HiveMQ Platform
Open Analyze and the Data Health tab. Total traffic splits into governed and ungoverned traffic. Governed traffic splits into healthy traffic, which matches the expected types and structure, and deviating traffic. The Deviations tab shows the details. Values that do not match the expected type are skipped and flagged. Governed traffic can show up with a delay.
Check this before you share the number. If a PLC starts to send text where the namespace expects a number, the OEE underneath changes silently, and Data Health is where you see it first.
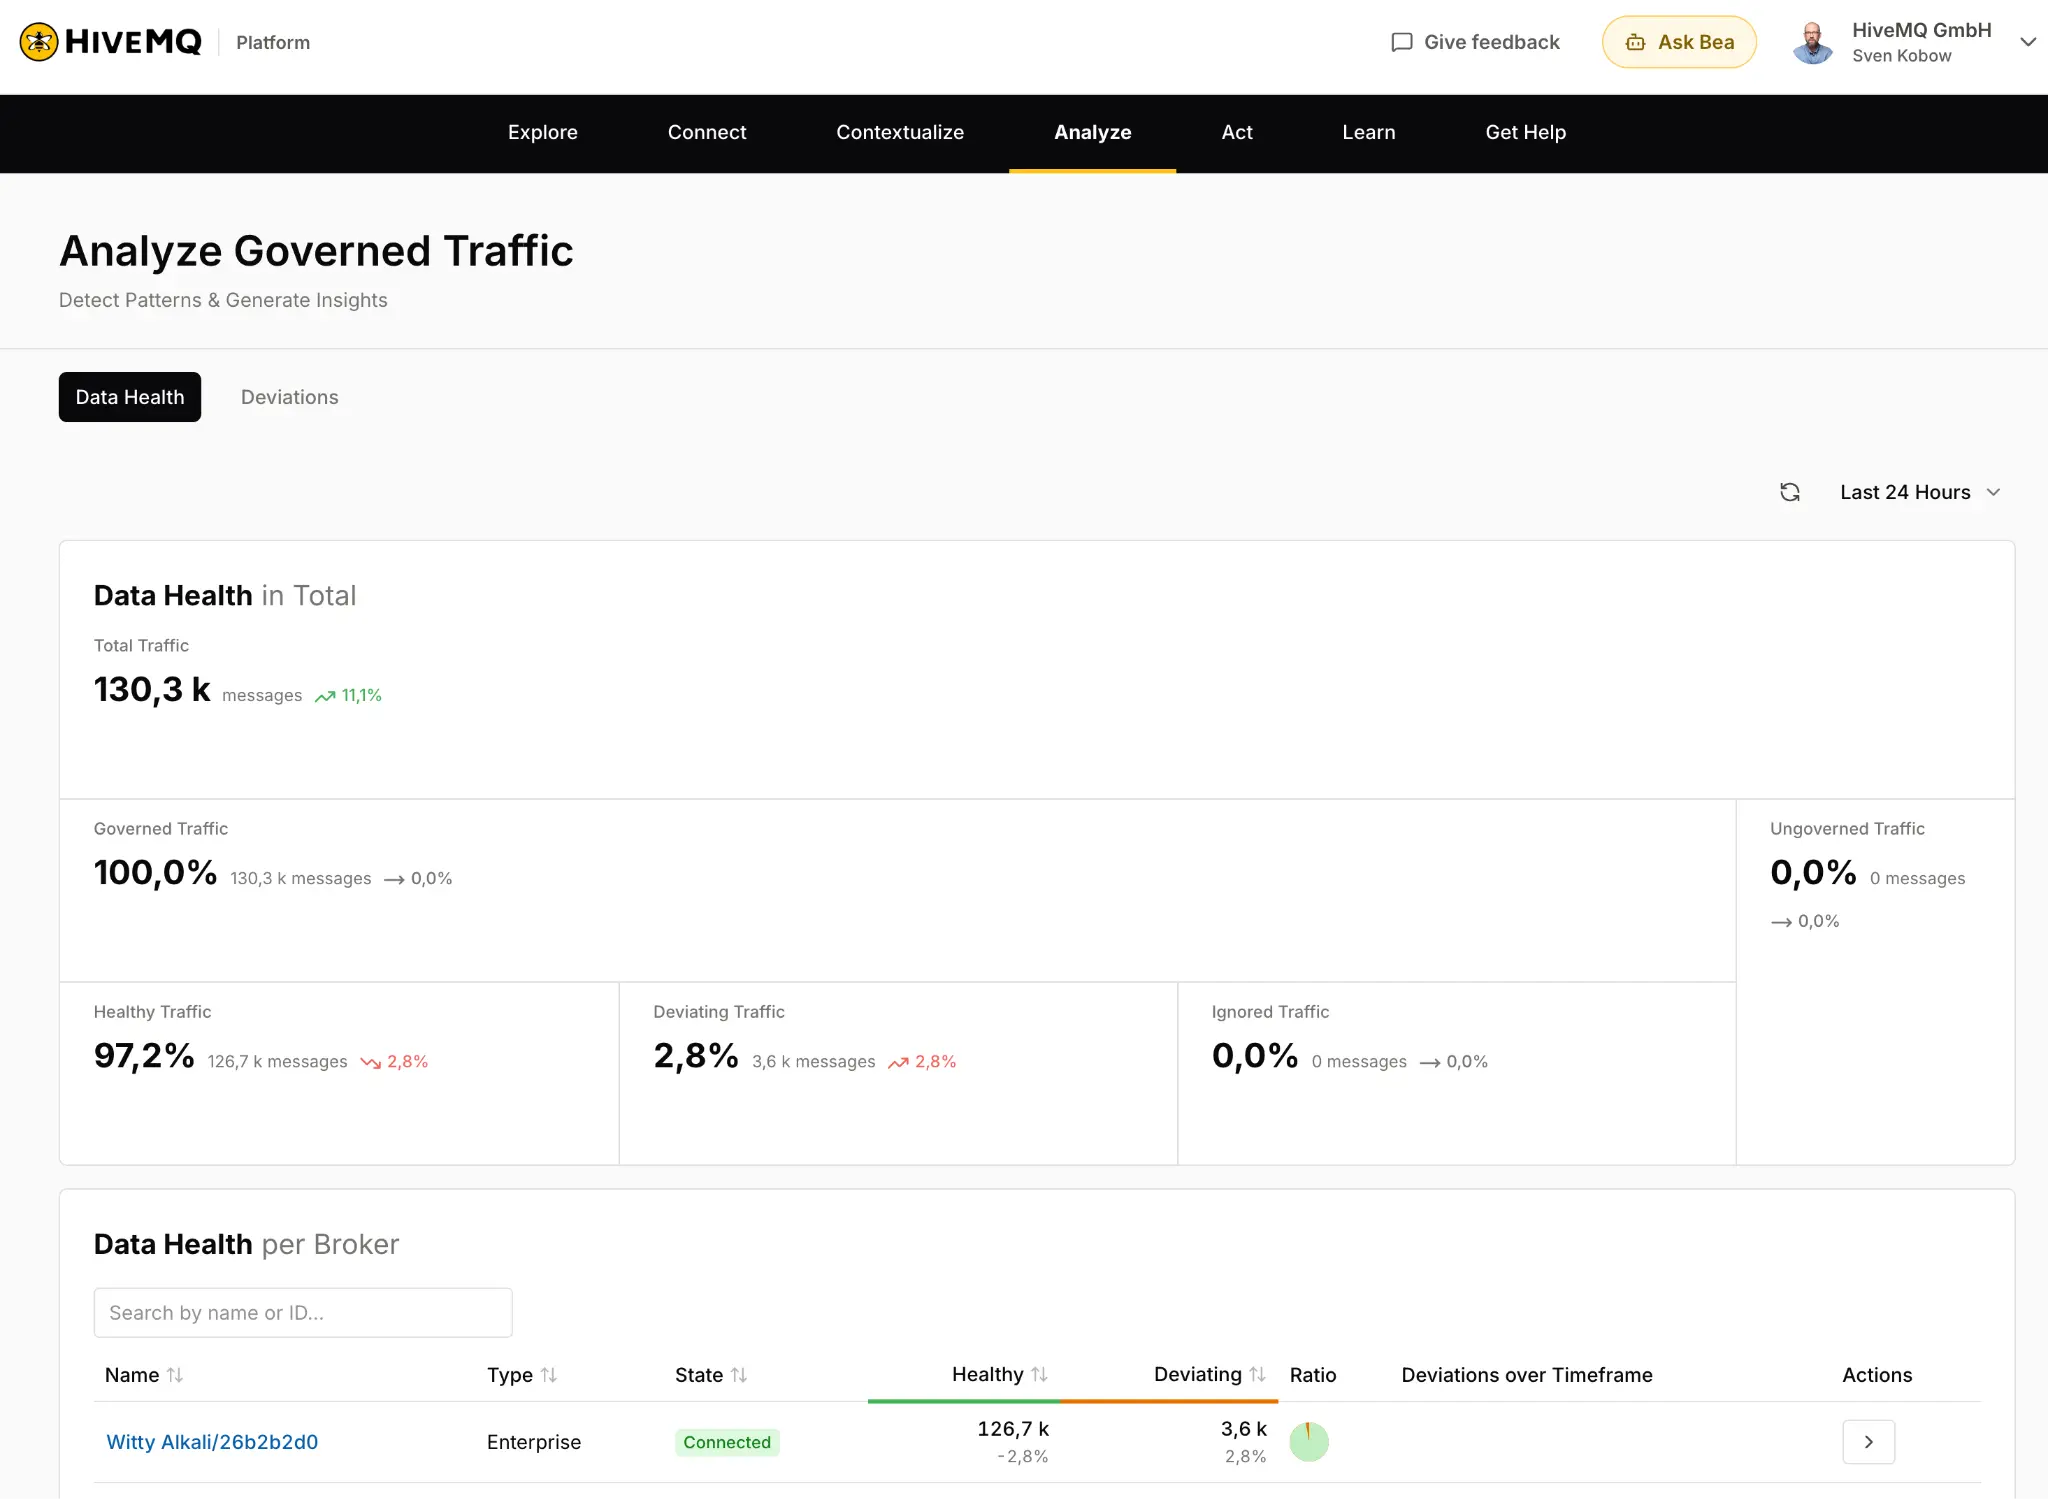
The Data Health tab with governed, ungoverned, healthy and deviating traffic
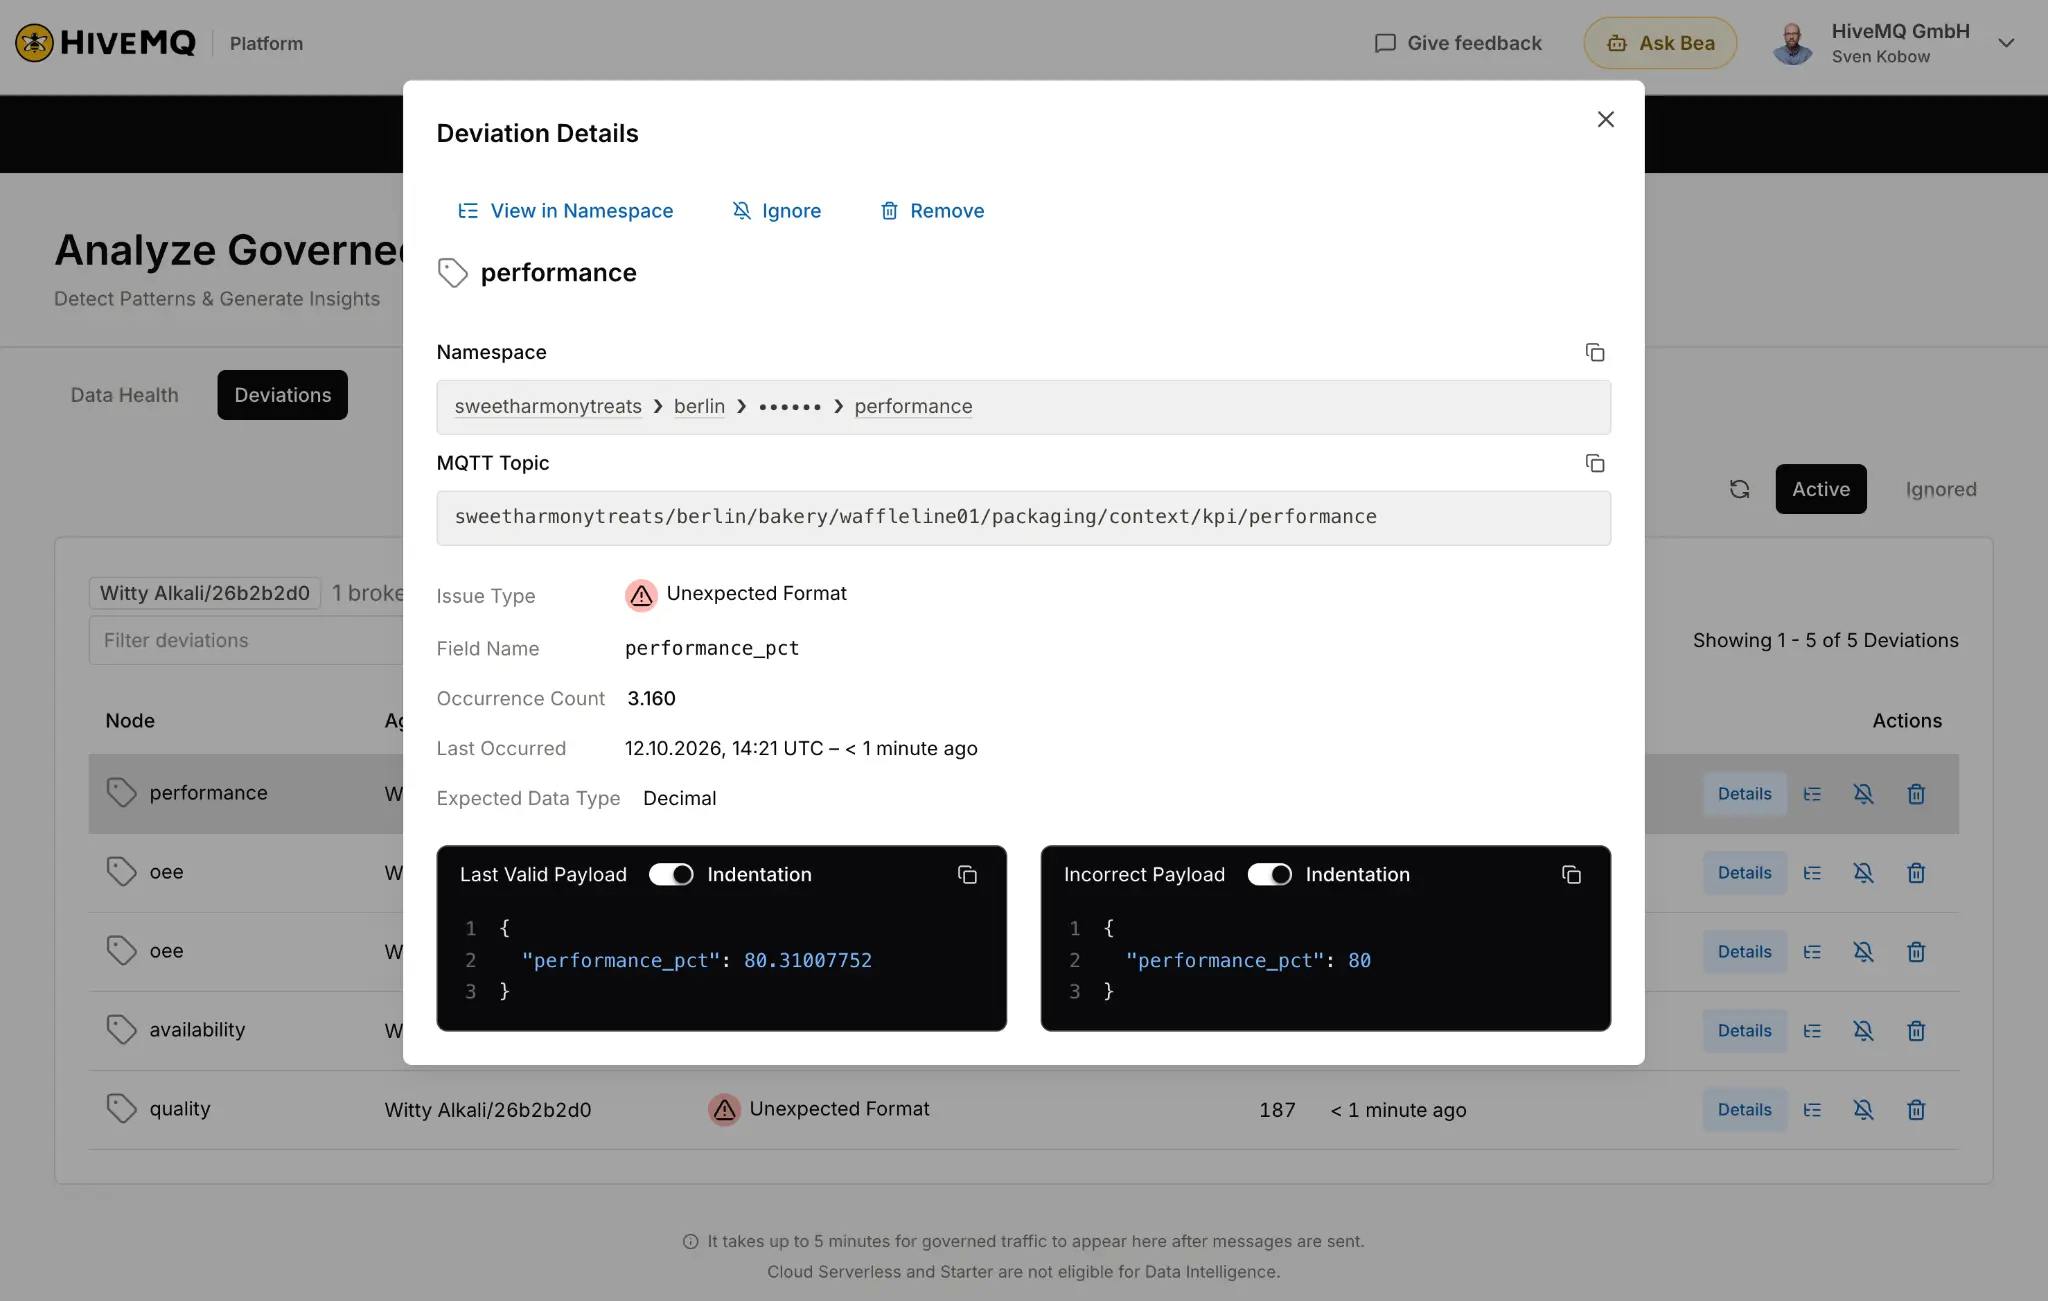
The Deviations tab with the details of non-matching values
How UNS in HiveMQ makes OEE data available to downstream and AI systems in manufacturing
The result is a tag in the namespace, in the context/kpi branch of the cell. Dashboards, the MES, a historian or an AI agent read it from there, and none of them needs its own interface to the PLC, the MES or the ERP. A Grafana dashboard with an MQTT data source, for example, can show the three factors and the OEE live, as soon as the cell publishes them. That is what makes the namespace an integration point: each source publishes once, and every consumer uses the same governed data. There is one more consumer worth a closer look. An OEE of 56 percent tells a person that something is wrong. But what if an AI agent could read the same tag, check it against the state, the production order and the machine data around it, and work out why the value is low and what to do about it? Because the result sits next to the raw data and the business context in one governed structure, an agent finds everything it needs in one place.
That is the idea behind the Act layer of the HiveMQ Platform, and it is the topic of a later article in this series: from a calculated KPI to agents that act on it.
What comes next: From a calculated Manufacturing KPI to AI agents that can act
Connect moved the data, and Contextualize gave it structure, meaning and a first KPI. The next article in this series covers Analyze: standardized KPIs across lines and sites, and what you can do once the data is governed.
Read the whitepaper this series builds on, Building a Scalable Data Foundation for Real-Time Operational Intelligence or explore the HiveMQ Platform and build your own unified namespace.