 TL;DR
Data lineage for manufacturing traces every sensor reading from edge to system of record, so quality teams can find root causes faster and stay audit-ready.
- Organizations implementing end-to-end message tracing across OT and IT boundaries report faster mean-time-to-resolution for data quality incidents and fewer compliance documentation gaps.
- HiveMQ's streaming foundation, combined with HiveMQ Data Intelligence's Semantic Graph, enables architects to move from reactive "where did this value come from?" investigations to proactive, governed data lineage that is always on.
- True data lineage is not observability bolted on after the fact; it is an architectural discipline that must be designed into the messaging infrastructure from day one.
Who this blog is for: IT/OT solutions architects building end-to-end message tracing into manufacturing data infrastructure.
Every manufacturing organization that operates at scale eventually confronts the same question: a suspect value appears in the MES, the quality system flags an anomaly, or a regulatory auditor requests proof of measurement integrity, and the team needs to reconstruct exactly how a specific reading traveled from a sensor on the shop floor to the system of record.
Data lineage answers that question systematically rather than forensically. In MQTT-based architectures, where publish/subscribe decoupling is a feature, lineage requires deliberate design. This article provides a technical framework for IT/OT solutions architects building end-to-end message tracing into manufacturing data infrastructure.
Why does data lineage matter more in manufacturing than in enterprise IT?
In a typical enterprise application stack, a request-response pattern creates an implicit trace: a REST call hits an API gateway, reaches a microservice, writes to a database, and returns. The call chain is linear and synchronous. Distributed tracing tools like OpenTelemetry instrument these hops with span contexts that propagate automatically.
Manufacturing architectures are fundamentally different. A temperature reading from a thermocouple on a pharmaceutical reactor might follow this path:
- PLC samples the analog input at 100 ms intervals.
- An OPC UA server aggregates and publishes the value.
- HiveMQ platform translates the OPC UA node into an MQTT message on a structured topic (e.g., site/plant-3/area-2/reactor-7/temperature/jacket).
- The HiveMQ Broker receives the message, applies validation policies, and fans it out to multiple subscribers.
- A stream processor enriches the reading with batch context from the ERP system.
- The enriched record lands in a historian, a real-time dashboard, and a quality management system simultaneously.
At every hop, the message can be transformed, filtered, aggregated or duplicated. The pub/sub model means producers and consumers are decoupled by design; there is no call chain linking them. Without deliberate lineage instrumentation, reconstructing that path after the fact ranges from expensive to impossible.
Regulatory pressure compounds the challenge. FDA 21 CFR Part 11, EU Annex 11, and ISO 9001 all require demonstrable data integrity. Auditors do not accept "we think the value came from reactor 7." They require provenance: what device produced the measurement, when, through which systems it traveled and whether any transformation altered it.
What is end-to-end message tracing in an MQTT architecture?
End-to-end message tracing is the capability to follow a single data point (or a batch of correlated data points) from its origin at a physical sensor through every system that touches it until it reaches its final destination, with a complete, immutable record of each transformation applied along the way.
In MQTT-based systems, this requires solving three problems that the protocol itself does not address natively:
1. Context propagation across pub/sub boundaries
In request-response systems, trace context (a trace ID, span ID, and baggage) rides along with the request headers. MQTT 5 introduced User Properties on PUBLISH packets, which provide the mechanism for attaching trace context to messages. MQTT v3.1.1 requires encoding context within the payload itself, which is more invasive but workable.
The architectural decision is where context originates. For manufacturing lineage, the context should be minted as close to the physical measurement as possible. If HiveMQ platform is performing protocol translation from OPC UA or Modbus, it is the natural instrumentation point: the edge gateway assigns a unique lineage ID and initial metadata (source device, timestamp, data quality indicator) before the message enters the MQTT topic namespace.
2. Transformation tracking
A raw sensor value of 78.3 is not the same data point after it has been unit-converted to Celsius, validated against a range policy, enriched with batch ID context, and averaged into a 5-minute rolling window. Each transformation must be recorded as a lineage event: what operation was applied, by which component, at what time, and what the value was before and after.
HiveMQ Data Intelligence policies are a critical instrumentation point here. When a policy validates, transforms, or routes a message, that policy execution is itself a lineage event. Architects should design Data Intelligence policies to emit lineage metadata (policy name, version, action taken, pass/fail result) as MQTT User Properties or as sidecar messages on a dedicated lineage topic.
3. Fan-out correlation
When the MQTT broker delivers a single published message to five subscribers, each subscriber receives its own copy. Lineage must track that these five downstream records share a common ancestor. This is the "fan-out correlation" problem, and it requires that the lineage ID assigned at origin persists through delivery. The broker does not modify User Properties during fan-out, so as long as the originating context is attached, correlation is preserved at the MQTT layer. The challenge arises when subscribers strip or fail to propagate the lineage context into their own downstream systems.
How should architects design a data lineage-aware topic namespace?
Topic namespace design is the single highest-leverage decision for data lineage in MQTT architectures. A well-designed namespace makes lineage queries efficient; a poorly designed one makes them expensive or impossible.
Consider an ISA-95-aligned topic structure as the starting point:
{enterprise}/{site}/{area}/{line}/{cell}/{measurement-type}For lineage purposes, this structure provides spatial provenance inherently. A message on acme/plant-detroit/stamping/line-4/press-12/tonnage encodes its physical origin in the topic path. But spatial provenance is only one dimension. Temporal provenance (when), causal provenance (why), and transformational provenance (how it changed) must be captured in the message metadata.
A lineage-aware message envelope (using MQTT v5 User Properties) might include:
| User Property Key | Example Value | Purpose |
|---|---|---|
| lineage-id | a3f8c9e1-7b2d-4f5a-9c1e-2d3b4a5f6e7d | Unique ID minted at origin, propagated through all hops |
| origin-device | press-12-tonnage-sensor-01 | Physical device that produced the measurement |
| origin-timestamp | 2025-01-15T08:32:17.432Z | Timestamp at measurement source, not at broker receipt |
| hop-count | 3 | Number of systems that have processed this message |
| last-transform | datahub:unit-conversion-v2.1 | Most recent transformation applied |
| data-quality | GOOD | OPC UA-style quality indicator carried forward |
This approach enables lineage queries without requiring a separate lineage store for basic investigations. For complex lineage analysis (full graph traversal, impact analysis, regulatory reporting), a dedicated lineage service subscribing to a $lineage/# topic can aggregate and index these metadata points.
For a deeper look at how MQTT topic structures and the Unified Namespace provide semantic structure for industrial data, read our blog, Semantic Data Structuring with MQTT Sparkplug and Unified Namespace.
How does HiveMQ Data Intelligence transform lineage from instrumentation to intelligence?
Instrumenting messages with lineage metadata is necessary but not sufficient. Raw lineage events are the equivalent of raw log files: useful for forensic investigations but not for proactive governance. This is where the Data Intelligence layer elevates lineage from a debugging tool to a strategic capability.
HiveMQ Data Intelligence's Semantic Graph provides three capabilities that transform lineage data:
Automated discovery and cataloging of industrial data
Data Intelligence discovers data sources, topics, and message schemas across the MQTT namespace automatically. For lineage, this means the Semantic Graph knows not just that a topic exists, but what entity it represents, what schema its payloads conform to, and which upstream and downstream systems interact with it. An architect does not need to manually maintain a lineage map; the graph reflects operational reality continuously.
Semantic context for lineage events
A lineage event that says "message transformed by policy unit-conversion-v2.1" is useful. A lineage event that says "the jacket temperature measurement for Reactor 7 in Batch B-2025-0142 was converted from Fahrenheit to Celsius by the site-standard unit normalization policy, version 2.1, as required by the EU Annex 11 compliance framework" is actionable. Data Intelligence's semantic modeling maps raw lineage metadata to business-meaningful entities, relationships, and governance policies. The Semantic Graph connects the technical lineage (message hops) to the business lineage (what product, what process, what regulation). For a deeper look at adding operational context and meaning to industrial data, read our blog, Contextual Modeling Strategies to Reduce Manufacturing Data Volume.
Governance policy enforcement
Data Intelligence enables governance policies that operate on lineage itself. Examples:
- Completeness policies: Alert if a message reaches the historian without a lineage-id or origin-device property. Prevents ungoverned data from entering systems of record.
- Transformation audit policies: Require that any message modified by more than N transformations triggers a review workflow before it is used in quality decisions.
- Retention policies: Ensure lineage metadata is retained for the duration required by the applicable regulatory framework (e.g., 7 years for pharmaceutical batch records under FDA guidelines).
This is the architectural shift from "we can trace data when something goes wrong" to "our data infrastructure enforces traceability as a continuous, governed discipline."
Conceptual reference architecture for end-to-end data lineage in smart manufacturing
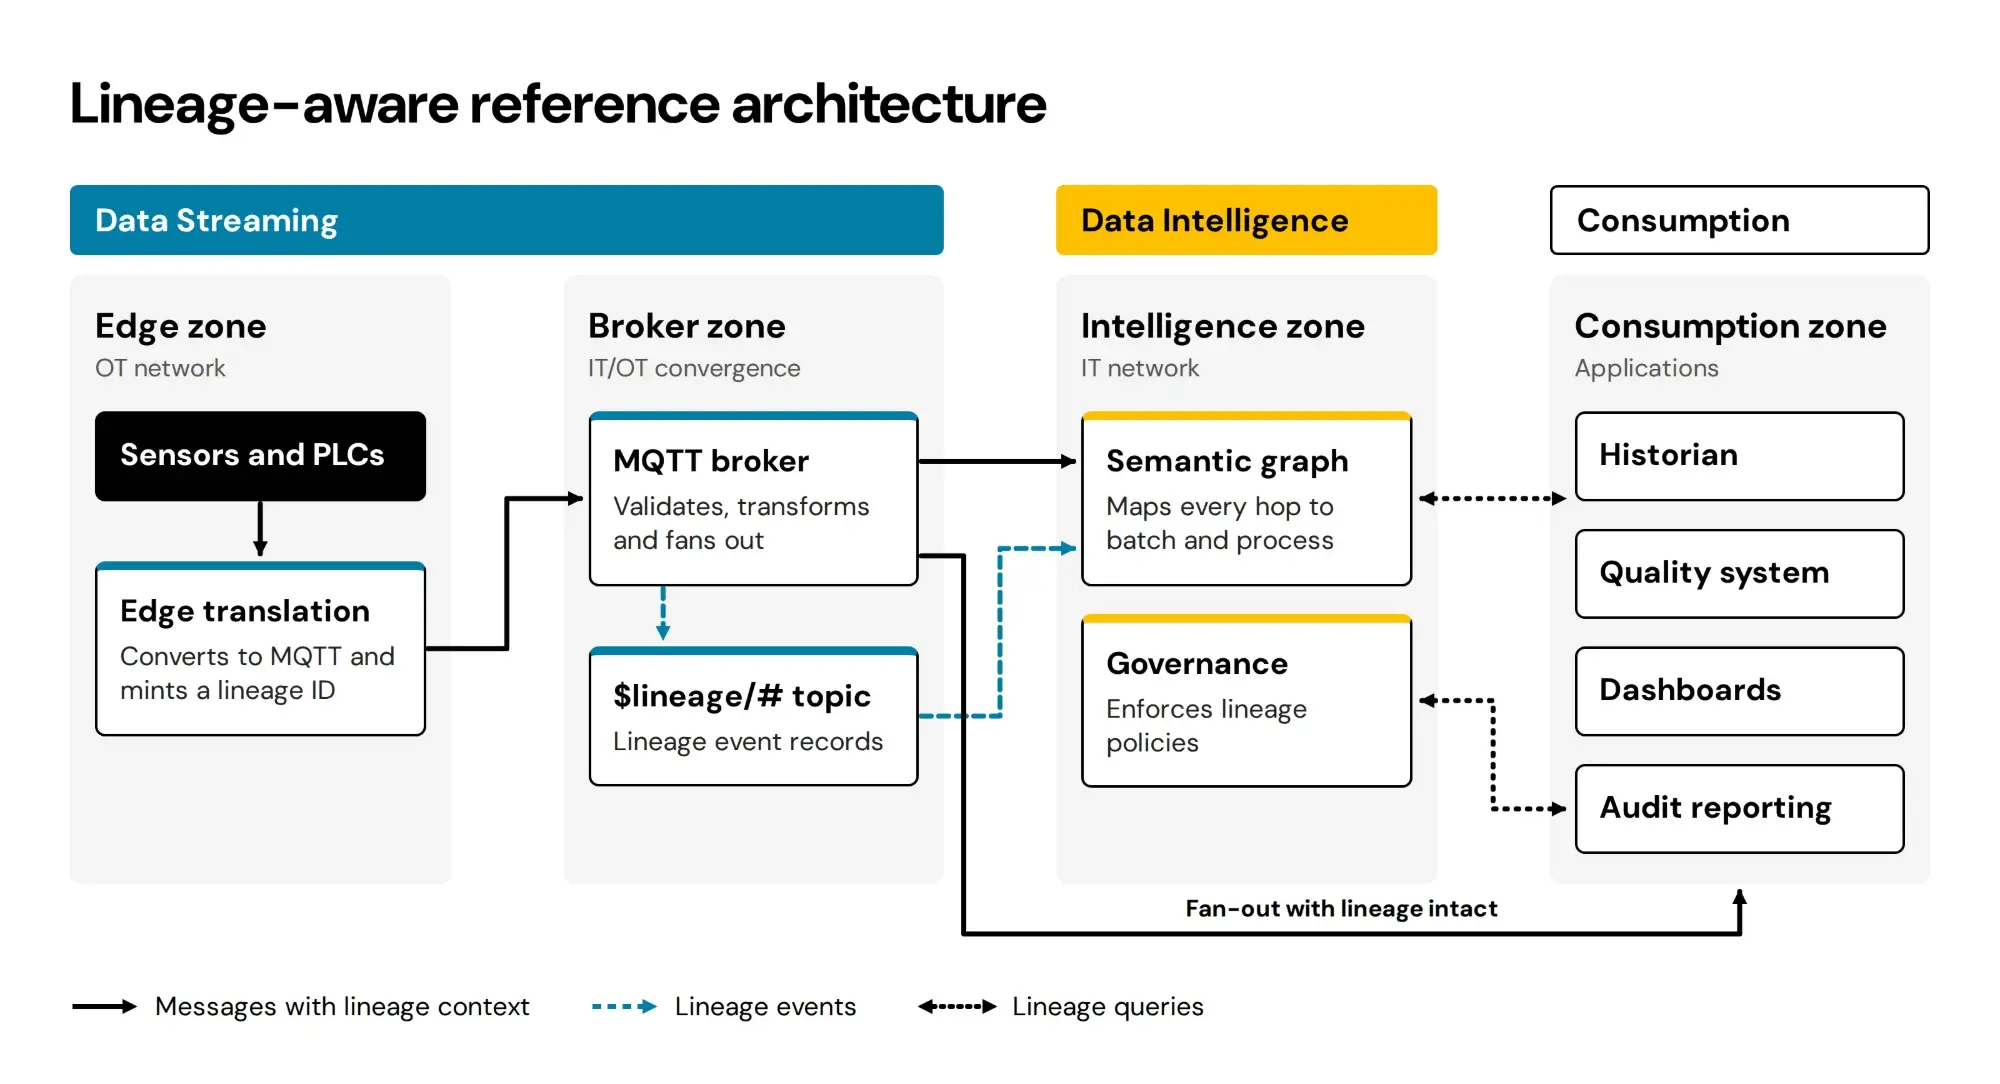
For an IT/OT solutions architect designing a lineage-aware manufacturing data platform, the reference architecture has four zones:
Edge zone (OT network)
- HiveMQ Platform performs protocol translation (OPC UA, Modbus, Siemens S7) and mints lineage IDs at the point of ingestion.
- Edge policies validate data quality indicators and attach origin metadata.
- MQTT v5 User Properties carry lineage context from the edge to the broker cluster.
Broker zone (DMZ / convergence layer)
- HiveMQ Broker (part of the Connect layer) cluster receives messages, applies Data Intelligence validation and transformation policies, and fans out to subscribers.
- Data Intelligence policies are instrumented to emit lineage events (policy name, version, action, result) as User Properties on the forwarded message.
- A dedicated $lineage/# topic namespace carries detailed lineage event records for downstream indexing.
Intelligence zone (IT network)
- HiveMQ Data Intelligence subscribes to operational and lineage topics, populates the Semantic Graph with discovered entities and relationships, and enforces governance policies.
- Lineage queries are resolved against the Semantic Graph: "Show me every system that touched Batch B-2025-0142 temperature data" returns a traversable graph, not a flat log.
- Anomaly detection identifies lineage pattern deviations (e.g., a message that normally traverses 3 hops suddenly traversing 5, indicating an unexpected routing change).
Consumption zone (applications)
- Historians, quality management systems, dashboards, and analytics platforms receive messages with lineage context intact.
- Each consuming application can verify provenance before trusting a data point for decisions.
- Regulatory reporting tools query the Semantic Graph for audit-ready lineage documentation.
How does lineage accelerate debugging across OT/IT boundaries?
Consider a concrete scenario. A quality engineer at an automotive stamping plant notices that tonnage readings for Press 12 on Line 4 are showing intermittent spikes in the quality management system. The readings trigger false quality holds, delaying production.
Without lineage: The investigation starts with the quality system and works backward. Is the spike in the historian? Yes. Is it in the broker? Someone checks the broker logs manually. Is it in the OPC UA server? An OT engineer is dispatched to check. Is it the sensor? A maintenance technician inspects the physical device. This process takes hours or days, involves multiple teams, and often resolves inconclusively with "we'll monitor it."
With lineage: The quality engineer queries the Semantic Graph: "Show lineage for tonnage messages from press-12 where value exceeds threshold in the last 24 hours." The graph returns:
- Origin: Sensor press-12-tonnage-01, value 245.7 tons, quality GOOD, timestamp 08:32:17.432Z.
- Hop 1: HiveMQ Platform, OPC UA translation, no transformation, value unchanged.
- Hop 2: HiveMQ Broker, Data Intelligence policy stamping-range-check-v3.2, validation result PASS (range 50-300 tons).
- Hop 3: Stream processor, enrichment with batch context, unit conversion applied (short tons to metric tons), output value 222.9 tonnes.
- Hop 4: Quality management system, threshold comparison against spec max 200 tonnes, result FAIL.
The root cause is immediately visible: the unit conversion from short tons to metric tons is correct, but the quality system threshold was configured in metric tonnes while the original spec was written in short tons. The lineage trace pinpoints the exact hop where the semantic mismatch occurs. Resolution time drops from days to minutes.
How manufacturing data lineage strengthens governance and compliance, beyond debugging
Data lineage, when implemented as a continuous architectural discipline rather than a forensic tool, enables governance capabilities that are difficult or impossible to achieve otherwise:
Impact analysis before changes. Before modifying a Data Intelligence policy, upgrading an edge gateway, or changing a topic namespace structure, architects can query the Semantic Graph to understand exactly which downstream systems and processes depend on the affected data flow. This transforms change management from risk-laden guesswork to informed decision-making.
Compliance automation. Regulatory audits that previously required weeks of manual documentation assembly can be satisfied by querying the lineage graph for a specific batch, time period, or measurement type. The lineage record is continuous and immutable; it does not depend on someone remembering to document a process.
Data quality scoring. Lineage metadata enables automated data quality scoring: a message that has traversed its expected path with all transformations validated scores higher than one that took an unexpected route or bypassed a validation policy. Consuming applications can use this score to make trust decisions programmatically.
Cross-site standardization. For multi-plant manufacturers, lineage reveals inconsistencies in how different sites handle the same data types. If Plant A applies three transformations to temperature data before storage and Plant B applies five, the lineage graph makes this visible and actionable.
Conclusion
Data lineage is not a feature you bolt onto a manufacturing data architecture after deployment. It is an architectural discipline that must be designed into the messaging infrastructure from the outset. The combination of HiveMQ's streaming foundation (protocol translation at the edge, policy-driven transformation at the broker, reliable fan-out to consumers) with Data Intelligence's Semantic Graph (automated discovery, semantic context, governance enforcement) provides the only platform that treats lineage as a first-class, continuous capability rather than an afterthought.
For IT/OT solutions architects designing the next generation of manufacturing data platforms, the question is not whether you need data lineage. The question is whether you build it into the foundation now or pay exponentially more to retrofit it later.
Schedule a consultation with a HiveMQ solutions architect to discuss how end-to-end data lineage fits into your manufacturing data strategy.
